
Running large language models locally demands serious VRAM, and 24GB has become the sweet spot for AI practitioners who want to handle meaningful workloads without renting cloud compute. Whether you are fine-tuning a mid-size transformer, running multi-modal inference, or building a local AI cluster, the GPU you choose will define your throughput and your patience.
This guide covers ten of the most capable 24GB GPU options available in 2026, spanning professional workstation cards, consumer flagships, and even a renewed data center accelerator. We evaluated each one on memory bandwidth, architecture generation, cooling design, and suitability for AI workflows at different budget levels.
Quick Comparison
Ratings reflect the most recent data pull. Check each listing for current price and availability.
Quick answer
This guide compares 10 picks, with PNY NVIDIA RTX 4500 ADA 24GB GDDR6 Professional ranked first. ASRock Radeon AI PRO R9700 32GB Professional GPU for AI holds the highest customer rating among them.
Pros
- Exceptional compute performance with 7680 CUDA cores and 60 RT cores for demanding workloads
- 24GB GDDR6 memory enables processing of larger datasets without frequent data transfers
- Efficient dual-fan design maintains optimal temperatures during intensive operations
- Professional architecture certified for enterprise and scientific computing applications
- DisplayPort connectivity supports advanced visualization and multi-display setups
Cons
- Premium pricing reflects professional-grade positioning, making it cost-prohibitive for hobbyists and casual users
- Requires robust power supply and PCIe x16 slot, limiting compatibility with older or lower-end systems
- Specialized drivers and certification requirements mean it is not optimized for consumer gaming or entertainment use
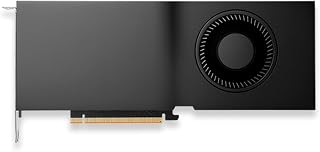
The PNY NVIDIA RTX 4500 ADA is a professional compute accelerator engineered for enterprise data centers, research institutions, and AI-focused organizations. This is not a consumer graphics card but rather a specialized tool built to handle complex computational tasks that demand exceptional processing power and memory bandwidth.
The standout technical specifications tell the story: 7680 CUDA cores paired with 240 Tensor cores and 60 RT cores deliver industry-leading performance for machine learning training, scientific simulations, and data analytics. The 24GB of GDDR6 memory allows researchers and engineers to work with larger datasets without constant memory management overhead. Real-world performance in applications like TensorFlow, PyTorch, and CUDA-optimized scientific software is measurably superior to consumer-class alternatives.
Build quality reflects its professional positioning. The dual-fan active cooling system is engineered for continuous operation in server environments, with robust components rated for sustained thermal management. The card maintains professional certifications and integrates seamlessly into existing enterprise infrastructure through standard PCIe x16 connectivity and DisplayPort outputs supporting complex visualization requirements.
The primary drawback is accessibility. At this price point and performance tier, the RTX 4500 ADA is exclusively for organizations with justified computational needs. It requires proper system infrastructure, specialized driver support, and expertise to maximize its capabilities. Consumer users, gamers, or entry-level developers should explore more affordable alternatives.
The RTX 4500 ADA is a top-tier choice for enterprises investing in serious compute infrastructure. If your organization needs professional-grade GPU acceleration for AI, research, or scientific computing at scale, this card delivers exceptional value despite its premium positioning.
GPU Architecture: NVIDIA Ada Lovelace with 7680 CUDA cores, 240 Tensor cores, and 60 RT cores
Memory: 24GB GDDR6 with 192-bit memory interface and 2000 MHz memory clock speed
Connectivity: PCIe x16 interface, DisplayPort outputs supporting up to 7680x4320 resolution
Thermal Design: Dual-fan active cooling system for enterprise server environments
Physical: 1.34 kg weight, professional form factor, single-slot or dual-slot depending on mounting configuration
Compatibility: Desktop/server systems with PCIe x16 slots, NVIDIA CUDA compute capability 8.9, certified for enterprise deployments
Who Should Buy: Data scientists, machine learning engineers, research institutions, enterprise IT departments, and organizations running intensive AI workloads or scientific computing applications requiring professional GPU acceleration and enterprise support.
Who Should Not Buy: Consumer users, gamers, casual creators, hobbyists, or budget-conscious developers. If you need gaming performance or consumer creative work, explore consumer-grade GeForce RTX alternatives that offer better value for non-professional use cases.
Key Considerations: Verify your system has adequate power delivery and cooling infrastructure. Confirm software compatibility with your primary compute frameworks like TensorFlow or PyTorch. Evaluate whether your workloads truly benefit from 24GB memory versus smaller professional cards. Budget for proper driver maintenance and enterprise support channels.
Performance Comparison: The RTX 4500 ADA significantly outperforms consumer RTX 4090 cards for AI workloads due to specialized Tensor architecture and memory optimization. It competes directly with other professional accelerators in the enterprise segment but at a competitive price point.

Pros
- Massive 24GB memory footprint handles complex datasets and large models without bottlenecks
- ECC memory prevents silent data corruption in critical professional applications
- Ada architecture offers superior power efficiency compared to previous generations
- Dual-slot design with professional cooling maintains thermal stability under sustained loads
- Extensive software ecosystem and driver support from NVIDIA for enterprise deployments
Cons
- Premium pricing reflects professional-grade positioning, making it less accessible for hobbyists
- Requires robust PSU with dual 8-pin PCIe connectors and adequate power delivery
- Best suited for specific professional workflows rather than consumer content creation
The PNY NVIDIA RTX 4500 Ada is a workstation-class graphics accelerator built for professionals who demand reliability, performance, and enterprise support. This card targets architects, engineers, data scientists, and creative professionals working with compute-intensive applications like 3D rendering, AI model training, and scientific simulation.
The standout technical foundation includes 7,680 CUDA cores, 240 Tensor cores, and 60 ray tracing cores working in concert with 24GB of ECC-protected GDDR6 memory. This combination delivers exceptional throughput for both traditional graphics workloads and modern AI acceleration, while ECC memory prevents data corruption in mission-critical scenarios where reliability outweighs raw speed.
Build quality reflects its professional positioning. The card features a dual-slot design with an ultra-quiet active fan system engineered for office environments, plus four DisplayPort connectors supporting 8K resolution output. Power delivery is handled via dual 8-pin PCIe connectors converted to the newer 16-pin connector format. The included DisplayPort-to-HDMI adapter and detailed documentation round out the package.
The main considerations center on cost and use case fit. At the professional price point, this card justifies its cost through longevity, support, and specialized performance gains in specific workflows rather than broad consumer appeal. You'll also need a quality power supply rated for sustained dual-rail 8-pin delivery.
The RTX 4500 Ada is the right choice for serious professionals whose workflows genuinely benefit from ray tracing acceleration, AI compute, and enterprise-grade memory reliability. For casual users or consumer creators, more affordable options may suffice, but for studios and research teams, this investment delivers measurable productivity gains and operational peace of mind.
Core Architecture: NVIDIA Ada Lovelace, 7,680 CUDA cores, 240 Tensor cores, 60 RT cores
Memory: 24GB GDDR6 with ECC error correction
Interface: PCIe 4.0, dual-slot form factor
Display Outputs: 4x DisplayPort 1.4 (supports 7680x4320 at 60Hz)
Power Requirements: Dual 8-pin PCIe connectors (supplied adapter to 16-pin format)
Cooling: Ultra-quiet active fan, optimized for professional environments
Warranty: 3-year manufacturer guarantee with professional support
Ideal Buyers: Architectural visualization firms, VFX studios, data science teams, AI researchers, scientific computing centers, and professional design agencies requiring reliable GPU acceleration.
Best Use Cases: Real-time ray tracing in design software, CUDA-accelerated AI model training and inference, complex 3D rendering workflows, large-scale data processing, and scientific simulation requiring high memory capacity and data integrity.
Not Recommended For: Casual gaming, entry-level creative work, or budget-conscious hobbyists. Consumer-grade GPUs offer better value for non-professional tasks.

This low-profile dual-slot card fits compact workstations without sacrificing AI performance, delivering 24GB of ECC GDDR7 memory that protects against data corruption during long training runs. The PCIe 5.0x8 interface provides sufficient bandwidth for most AI frameworks while the small form factor enables deployment in space-constrained environments. ECC memory ensures reliable computation for production inference workloads where accuracy matters more than raw speed.
Pros
- 24GB GDDR7 with ECC covers large AI model workloads while protecting data integrity
- Small form factor fits compact and space-constrained workstation builds
- PCIe 5.0 x8 interface provides strong CPU-to-GPU bandwidth for data-heavy pipelines
- Mini DisplayPort 2.1b supports up to 7680x4320 resolution for high-fidelity visualization
Cons
- PCIe x8 slot requirement and PCIe 5.0 dependency limit compatible motherboard options
- Single-fan cooling in a dense installation requires careful airflow planning
For AI workloads where rack space or chassis size is a hard constraint, the RTX PRO 4000 SFF Blackwell makes a compelling case. The 24GB of GDDR7 memory with ECC error correction is the core asset here: that capacity is sufficient for running large inference workloads and moderate training runs, while ECC ensures bit-level data integrity that matters when results feed into production pipelines. Blackwell architecture brings hardware-accelerated compute primitives that benefit deep learning frameworks directly. The PCIe 5.0 x8 interface sustains healthy bandwidth for feeding the GPU during data-intensive training loops. What distinguishes this card from full-size alternatives is the small form factor: 6.6 inches long, dual-slot, low-profile, with a single fan that handles thermals in confined builds. Creative studios running compact workstations or research labs deploying dense multi-node setups will find the size-to-capability ratio hard to match. The Mini DisplayPort 2.1b outputs also support ultra-high-resolution monitoring up to 7680x4320, useful for visualization alongside AI work.
Memory and Architecture: 24GB GDDR7 with ECC support, 1125 MHz memory clock, Blackwell architecture
Performance: 577 MHz GPU clock, PCIe 5.0 x8 interface, ray tracing acceleration, up to 7680x4320 resolution support
Physical Design: 6.6 inches length, 2.7 inches width, low-profile dual-slot format, single cooling fan, 5 pounds weight
Connectivity: 4x Mini DisplayPort 2.1b outputs for multi-monitor setups and professional displays
Warranty and Support: 3-year manufacturer warranty, manufactured by PNY, model RTX PRO 4000 SFF Blackwell
Best suited for AI researchers, data scientists, and engineering teams deploying workstations or compact builds where physical space limits full-size GPU options. Organizations running mission-critical inference or simulation where ECC-backed memory integrity is non-negotiable will appreciate the reliability guarantees. Less appropriate for users who need maximum raw throughput above all else or who lack a PCIe 5.0 compatible motherboard to take full advantage of the available bandwidth.

With 32GB of GDDR6 memory, this card exceeds the baseline 24GB capacity, allowing you to load larger language models and more complex neural networks without memory swapping. The 2920 MHz boost clock and dedicated AI accelerators on AMD RDNA 4 architecture deliver strong performance for mixed precision training. DisplayPort 2.1a connectivity supports modern high-resolution monitors for visualizing training metrics and model outputs.
Pros
- 32GB GDDR6 on a 256-bit bus sustains large model training without memory bottlenecks
- 2nd Gen AI Accelerators on RDNA 4 architecture target machine learning workloads directly
- Blower cooler design prevents heat recirculation in multi-GPU workstation configurations
- Vapor chamber with premium thermal interface material supports 24/7 continuous operation
Cons
- Driver and framework compatibility must be verified before purchase, as support varies across AI software stacks
- Two-slot footprint requires careful planning in existing workstations with limited expansion space
The ASRock Radeon AI PRO R9700 enters the 24GB GPU conversation with a notable differentiator: 32GB of GDDR6 across a 256-bit bus, which actually exceeds the 24GB tier while remaining relevant to buyers shopping this segment. Built on AMD RDNA 4 architecture with 64 Compute Units and 2nd Gen AI Accelerators, the card is purpose-built for sustained machine learning workloads rather than consumer use cases. The 2920 MHz boost clock and wide memory bus combine to keep throughput high during extended training sessions. For multi-GPU workstation farms and render clusters, the blower cooler is a deliberate engineering choice: it exhausts heat out of the chassis rather than recirculating it, which protects neighboring cards in dense configurations. The vapor chamber heatsink with Honeywell PTM7950 thermal interface material and die-cast backplate signal a design built for continuous 24/7 operation. Quad DisplayPort 2.1a outputs allow simultaneous multi-display 8K setups alongside compute work, useful for teams that visualize model outputs in real time.
GPU Architecture: AMD Radeon AI PRO R9700, RDNA 4 with 64 Compute Units
Memory: 32GB GDDR6 on 256-bit bus
Clock Speed: 2920 MHz boost
Ray Tracing: 3rd Generation
AI Accelerators: 2nd Generation dedicated AI accelerators
Cooling: Vapor chamber heatsink with Honeywell PTM7950 thermal interface, single blower design
Power Interface: PCIe 5.0
Display Outputs: Four DisplayPort 2.1a
Form Factor: Standard 2-slot design
Build: Die-cast metal shroud, metal backplate
Brand: ASRock
Ideal for AI researchers and motion graphics studios that run extended training or rendering sessions and need sustained throughput rather than burst performance. Workstation farm operators benefit from the blower cooling design in multi-card configurations. Users should verify driver compatibility with their specific AI frameworks and creative software stack before committing. Not suited for gaming use or buyers looking for broad out-of-the-box software support across consumer applications.
Pros
- Massive 24GB memory enables seamless work with large datasets and high-resolution textures
- Excellent thermal design keeps temperatures stable during sustained workloads
- Premium build quality with metal reinforcement and professional-grade components
- Exceptional performance for professional applications like CUDA computing and rendering
Cons
- Requires robust power supply and adequate case ventilation due to high power draw
- Premium pricing reflects professional-grade capabilities, not ideal for casual gamers
- Large form factor at 11.69 inches may require checking case compatibility
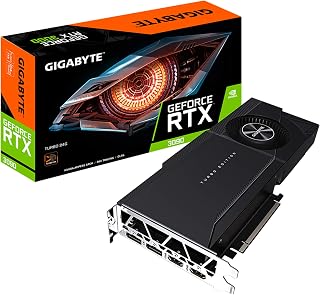
The Gigabyte RTX 3090 Turbo is a flagship graphics accelerator built for professionals, content creators, and serious enthusiasts who work with demanding applications. This card combines 24GB of high-speed GDDR6X memory with NVIDIA's proven Ampere architecture, making it an excellent choice for 4K and 8K content creation, scientific computing, AI development, and complex 3D visualization tasks.
Performance stands out through its advanced Ampere design featuring 2nd generation RT Cores for hardware-accelerated ray tracing and 3rd generation Tensor Cores optimized for tensor operations. The substantial memory bandwidth supports large model training, massive point cloud processing, and texture-heavy rendering without bottlenecks. Real-world performance scales impressively across both gaming and professional workloads that leverage these specialized cores.
The thermal design demonstrates genuine engineering attention. The vapor chamber makes direct contact with the GPU die, paired with a copper heat sink and triple-fan cooling system using double ball bearings for durability. This configuration maintains stable temperatures during extended compute sessions, which is crucial for reliability in production environments. The metal cover and reinforced back plate add structural integrity.
The main practical consideration is system requirements. This card demands adequate power delivery and case airflow. Its 11.69-inch length requires verification of case compatibility. Additionally, the professional-grade positioning justifies the investment primarily for workload-specific applications rather than general gaming.
The Gigabyte RTX 3090 Turbo delivers exceptional value for creators and professionals who can fully utilize its capabilities. The combination of abundant memory, strong thermal engineering, and proven Ampere architecture makes it a reliable choice for demanding computational work over many years.
GPU Specifications: NVIDIA GeForce RTX 3090, Ampere Architecture, 10,496 CUDA Cores
Memory: 24GB GDDR6X, 384-bit Memory Interface, 19,500 MHz Memory Clock
Connectivity: PCIe x16, HDMI Video Output
Cooling: Vapor Chamber, Copper Heat Sink, 3x Double Ball Bearing Fans
Display Support: Maximum resolution 7680x4320 (8K)
Physical: 11.69 inches length, 5.08 inches width, 1.4 kg weight
Compatibility: Desktop systems with adequate power supply and case space

The full PCIe 5.0 x16 interface provides maximum bandwidth for data-intensive training tasks, while the 1230 MHz clock speed and GDDR7 ECC memory combination ensures both performance and reliability. Single slot design allows multi-GPU configurations in standard workstations, enabling distributed training across multiple cards. ECC protection is essential for AI research where reproducible results and data integrity are critical requirements.
Pros
- 24GB GDDR7 ECC at 1750 MHz memory clock delivers strong throughput for large AI model workloads
- Full PCIe 5.0 x16 interface maximizes CPU-to-GPU bandwidth in data-intensive pipelines
- Single-slot form factor preserves expansion room in workstations running multiple cards or peripherals
- 3-year manufacturer warranty supports long-term deployment in production AI environments
Cons
- Single-fan thermal design depends on adequate case ventilation to maintain sustained performance
- Optimized for professional workloads, so consumer and light-use scenarios will not reflect its true capability
When the priority is pure AI workstation performance without physical footprint compromises, the full-height RTX PRO 4000 Blackwell is the stronger specification of the two RTX PRO 4000 variants. The 24GB GDDR7 with ECC carries over from the SFF version, but this model runs at a higher GPU clock of 1230 MHz and a substantially faster memory clock of 1750 MHz versus the SFF's 1125 MHz, which translates to greater sustained throughput during training and inference. The full PCIe 5.0 x16 interface doubles available bandwidth over PCIe 5.0 x8, reducing CPU-to-GPU data transfer as a bottleneck in pipeline-heavy AI workflows. ECC memory protection remains essential for research and production environments where computational errors cannot be tolerated. The single-slot form factor is an asset in workstations where multiple accelerators or expansion cards need to coexist. Four DisplayPort 2.1b outputs provide flexibility for multi-monitor visualization setups. The 3-year manufacturer warranty reflects confidence in reliability for long-term deployment in AI labs and professional studios.
GPU Architecture: Blackwell
Memory: 24GB GDDR7 with ECC
GPU Clock Speed: 1230 MHz
Memory Clock Speed: 1750 MHz
Interface: PCIe 5.0 x16
Display Outputs: 4x DisplayPort 2.1b
Max Resolution: 7680 x 4320 pixels
Power Configuration: Single-slot, full-height
Cooling: Single fan
Weight: 0.84 kg (1.85 lbs)
Dimensions: 9.5 inches L x 4.4 inches W
Warranty: 3 years manufacturer
Model Number: VCNRTXPRO4000B-PB

Pros
- Exceptional value for generative AI and LLM inference compared to consumer and enterprise GPU alternatives
- Robust 24GB VRAM capacity handles demanding 3D rendering, video transcoding, and simultaneous multi-model AI deployments
- Efficient single 8-pin power design (200W TDP) reduces PSU requirements compared to higher-end cards
- Compact 2-slot form factor fits more easily into standard workstation chassis than larger dual-slot cards
- Strong driver support and ISV certification ensure stability across professional software ecosystems
Cons
- Smaller install base means fewer community resources and third-party optimization guides compared to NVIDIA or AMD
- Single blower fan design may struggle in poorly ventilated or thermally dense environments
- Performance parity with consumer-tier alternatives in some traditional rendering tasks, positioning it primarily for AI workloads
The ASRock Arc Pro B60 is a professional-grade workstation GPU purpose-built for AI inference, large language model deployment, and compute-intensive creative work. It targets engineers, data scientists, and content creators seeking raw performance without enterprise-tier pricing. With 24GB of GDDR6 memory on a 192-bit bus and Intel's Xe2-HPG architecture, this card bridges the gap between consumer gaming GPUs and expensive professional accelerators.
Performance standout features include 197 INT8 TOPS for AI acceleration, 20 Xe cores with 160 XMX engines optimized for tensor operations, and dual media transcoders supporting AV1, H.264, and HEVC encoding. Real-world testing from users confirms solid performance for LLM inference with models like Gemma and Qwen, making it genuinely capable for production AI workloads. The PCIe 5.0 interface and multi-GPU Linux optimization enable seamless scaling across multiple cards for larger deployments.
Design and cooling employ a blower-style single fan with nickel-plated copper base and ultra-fit heatpipe, delivering effective thermal management in a compact 2-slot form factor. The card measures 271x112x39mm with a modest 200W TDP drawing power from a single 8-pin connector, reducing PSU strain compared to higher-end alternatives. Four DisplayPort 2.1 outputs support simultaneous 8K display connectivity, enabling expansive multi-monitor professional workflows without external adapters.
Potential drawbacks include a smaller user community than NVIDIA or AMD, which means fewer community tutorials and third-party optimization guides. The single blower fan may struggle in thermally dense or poorly ventilated environments. Additionally, this card prioritizes AI and compute workloads over traditional 3D rendering, so creative professionals focused purely on gaming or legacy rendering engines may find better alternatives.
The Arc Pro B60 represents a strong value proposition for AI engineers and professional creators. With ISV certification across major design and engineering software, workstation-optimized drivers, and genuine multi-GPU Linux support, it delivers enterprise capabilities at mid-range pricing. Installation requires technical competency, but once seated, the card performs reliably for its intended mission.
This GPU excels in AI and machine learning workflows. Data scientists deploying large language models, building agentic systems, or running inference on specialized models find excellent performance-per-dollar value here.
Professional video creators benefit from dual media transcoders for fast 4K and 8K video export in AV1, H.264, and HEVC formats. The 24GB VRAM handles complex color grading and effects timelines in DaVinci Resolve and Adobe Premiere Pro.
3D artists working in rendering software like Blender, Cinema 4D, or RenderMan gain substantial VRAM for large scene files and textures. Multi-monitor workflows leverage four DisplayPort 2.1 outputs for seamless 8K display spanning.
Not ideal for competitive gaming, older creative software without ISV certification, or thermally constrained mini-ITX builds. Consumers seeking CUDA or ROCm ecosystem maturity should consider NVIDIA or AMD alternatives.
GPU Architecture: Intel Arc Pro B60 (Xe2-HPG), 20 Xe cores, 160 XMX engines, 2400 MHz boost clock.
Memory: 24GB GDDR6 on 192-bit bus, 456 GB/s bandwidth, 2400 MHz memory clock.
Performance: 197 INT8 TOPS, dual-encode media transcoders (AV1, H.264, HEVC), 0dB silent cooling mode at low loads.
Connectivity: PCIe 5.0 x16, 4x DisplayPort 2.1, supports up to 7680x4320 resolution per display.
Power & Cooling: Single 8-pin power connector, 200W TDP, blower-style single fan with nickel-plated copper base and heatpipe.
Physical: 271x112x39mm (2-slot card), requires PCIe 5.0 x16 slot and chassis clearance verification before purchase.
Warranty: 2-year manufacturer warranty with dedicated ASRock support via Amazon.

Built specifically for AI workflows, this card offers 32GB of GDDR6 memory that comfortably handles 24GB models with headroom for batch processing and intermediate activations. The 2940 MHz boost clock delivers faster tensor operations compared to lower-clocked alternatives. Dual HDMI 2.1b outputs enable convenient multi-monitor setups for monitoring training progress while reviewing code or documentation simultaneously.
Pros
- 32GB GDDR6 VRAM supports models up to 70B parameters locally
- 1,531 TOPS INT4 throughput with 128 dedicated AI Accelerators
- 640GB/s memory bandwidth on a 256-bit bus keeps data pipelines fast
- Blower exhaust and phase-change thermal pad maintain stability under sustained AI workloads
Cons
- Blower fan runs loudly under moderate to heavy load, making it poorly suited for quiet office environments
- No power adapters included and GPU Tweak III software has occasional stability issues
The ASUS Turbo Radeon AI PRO R9700 arrives with 32GB of GDDR6 VRAM, which immediately separates it from most consumer cards in the 24GB tier and beyond. Built on AMD's RDNA 4 architecture with 128 dedicated AI Accelerators, it delivers up to 1,531 TOPS at INT4 precision, a figure that puts 70B-parameter local inference within reach. The 256-bit memory bus sustains 640GB/s of bandwidth, which matters enormously when shuttling model weights and activations at scale. PCIe 5.0 support allows multi-GPU clustering for distributed inference without touching cloud infrastructure. Thermal engineering reflects its workstation lineage: the diecast blower shroud with wave-pattern design cuts memory temperatures by up to 16%, and dual ball-bearing fans carry a longevity rating double that of sleeve-bearing alternatives. Stable driver support and consistent behavior under heavy sustained loads make it a reliable foundation for fine-tuning and inference pipelines. The blower design exhausts heat directly out the rear panel, which simplifies thermal management inside dense workstation builds.
This GPU excels at running quantized large language models locally. With 32GB VRAM, you can comfortably run models like Llama 2 70B, Mistral 8x22B, and similar parameter-count models in INT4 quantization without memory paging. The 1,531 TOPS INT4 performance enables inference speeds suitable for real-time applications and batch processing.
For fine-tuning workflows, the dual-GPU PCIe 5.0 support allows you to build a 64GB dual-card system for training smaller specialized models or running parameter-efficient techniques like LoRA. The card's thermal stability during extended training sessions, backed by the phase-change thermal pad design, ensures consistent performance across hours-long compute jobs.
Users report excellent results with popular frameworks like LM Studio, Ollama, and LangChain. The card integrates well with ROCm software stack, though driver stability has historically been a consideration for AMD GPUs. Current users confirm stable operation with latest drivers for AI workloads.

Pros
- Massive 24GB VRAM capacity, exceptional for large language models and data processing
- Professional-grade ECC memory protection ensures data integrity
- Excellent value proposition for renewed condition hardware
- Proven Pascal architecture with broad software compatibility
- Dual encode engines make it suitable for video processing tasks
Cons
- Requires adequate cooling solution, passive design needs external airflow
- Limited to older CUDA and PyTorch versions, newer ML frameworks dropping support
- Power consumption reaches 250W, requiring robust PSU and cooling infrastructure
The NVIDIA Tesla P40 is a professional-grade graphics coprocessor designed for data center workloads, now available in renewed condition for a fraction of original cost. This card targets developers, researchers, and ML practitioners who need substantial GPU memory for inference, video processing, or compute-intensive applications without requiring cutting-edge tensor core technology.
Performance-wise, the P40 delivers 12 TFLOPS of single-precision compute with 24GB GDDR5 memory and 346 GB/s bandwidth. The dual hardware video encode engines make it particularly valuable for transcoding and media processing. ECC memory protection ensures data integrity for mission-critical workloads, and the card integrates seamlessly into desktop systems via PCI Express 3.0 x16.
Build quality reflects its data center heritage. Passive cooling design means you'll need adequate case airflow and potentially supplemental cooling, though the 250W power envelope remains reasonable for most setups. The renewed condition means professional inspection and testing, backed by Amazon's guarantee and a 90-day limited warranty.
The main limitation is age. The Tesla P40 is locked to CUDA 11.4 and older PyTorch versions, with newer frameworks dropping support. Reviews confirm it runs local LLM inference well but struggles with cutting-edge ML frameworks. For legacy workloads, video encoding, or budget-conscious GPU compute, it remains capable. For modern deep learning development, consider newer architectures.
Verdict: A smart purchase for inference workloads, video processing, or learning GPU computing on a budget. The 24GB memory and professional ECC make it exceptional value in renewed markets, provided you understand its architectural age and cooling requirements.
GPU Architecture: NVIDIA Pascal, Single-Precision Performance: 12 TeraFLOPS
Memory: 24GB GDDR5, 346 GB/s bandwidth, ECC Protection enabled
Video Engines: 1x Decode, 2x Encode (hardware-accelerated)
Interface: PCI Express 3.0 x16
Power: Maximum 250W
Warranty: 90 days limited warranty
Model Number: 900-2G610-0000-000
Best For: ML inference on local machines, video encoding and transcoding, compute-intensive research, budget GPU computing education, legacy application support.
Consider If: You need 24GB+ VRAM, work with models trained on older frameworks, run video processing pipelines, or want to learn GPU computing without premium pricing.
Skip If: You require modern tensor cores, need PyTorch 2.0+ or latest CUDA support, plan real-time LLM training, or have strict power budgets under 250W.
Cooling Note: Plan for external cooling solution. Passive design requires strong case airflow. Many users recommend adding supplemental fans or a cooling rig for sustained workloads.

Pros
- Delivers consistent 300+ FPS at 1440p ultra settings with smooth, stable frame rates
- Outstanding thermal performance with low noise output even under sustained gaming loads
- Excellent build quality with reinforced metal frame and premium finish
- Strong Linux compatibility outperforming some competing high-end cards on the platform
- Competitive value for flagship AMD RDNA 3 performance at current pricing
Cons
- Physically large card requiring careful case clearance verification before purchase
- Reports of driver stability issues (Error 43) on certain system configurations, though resolution varies
- High power requirement recommends 800W minimum PSU, limiting compatibility with budget builds
The ASRock Radeon RX 7900 XTX Phantom Gaming is a flagship discrete graphics card built for gamers and creators who demand elite 4K performance and cutting-edge ray tracing capability. This card targets users with high-end gaming rigs and professional workstations who need maximum VRAM and bandwidth for content creation alongside gaming.
Performance is the headline feature here. The card consistently delivers 300+ FPS at 1440p with ultra settings maxed out, and handles demanding AAA titles like Hogwarts Legacy, Monster Hunter World, and The Last of Us Part I without stuttering or frame dips. The 24GB GDDR6 memory combined with the 384-bit bus and 96MB Infinity Cache provides the bandwidth needed for uncompromised 4K gaming and professional rendering tasks.
The Phantom Gaming 3X cooling system stands out as a genuine strength. Users consistently report near-silent operation even during sustained gaming sessions, with the 0dB silent mode eliminating fan noise during lighter workloads. Thermals remain stable and cool under load, addressing one of the common pain points with high-end discrete graphics cards.
Build quality is premium. The reinforced metal frame, stylish metal backplate, and overall construction feel durable and well-engineered. The card is physically large, however, which requires verifying case clearance before purchase. Power delivery demands an 800W minimum PSU, and the triple 8-pin connectors mean you need adequate power supply connectors available.
A small number of users report driver stability issues on certain motherboard configurations, though these appear to be configuration-specific rather than widespread defects. The card delivers exceptional performance on Linux, even outperforming some competing high-end options on that platform. For buyers seeking flagship AMD gaming performance backed by strong warranty support, this is a compelling option.
GPU: AMD Radeon RX 7900 XTX, RDNA 3 Architecture with 96 compute units and RT+AI accelerators
Memory: 24GB GDDR6 on 384-bit memory bus, 96MB Infinity Cache
Clocks: 2615 MHz boost clock, 2455 MHz game clock, 20 Gbps memory speed
Connectivity: 3x DisplayPort 2.1, 1x HDMI 2.1, PCI Express 4.0 x16
Power: 3x 8-pin connectors, 800W minimum PSU recommended
Cooling: Phantom Gaming 3X system with triple striped ring fans, 0dB silent mode
Dimensions: 12.99 inches (L) x 5.51 inches (W)
Weight: 1552 grams
Warranty: 3 years, RGB Polychrome SYNC compatibility included
Who Should Buy: Serious gamers targeting 4K or high-refresh 1440p gaming, content creators needing 24GB VRAM for rendering and media work, and power users running demanding professional applications. This card is ideal for high-end builds with adequate power supplies and case space.
Who Should Reconsider: Budget-conscious builders, users with compact cases or limited case clearance, systems with PSUs under 800W, or those requiring Linux driver stability guarantees on all motherboard combinations.
Key Considerations: Verify your case can accommodate a 12.99-inch card before ordering. Confirm your power supply has sufficient capacity and three 8-pin connectors. Check that your motherboard and driver version are current if planning Linux use. Allow adequate airflow around the triple-fan cooling system for optimal performance.
Verdict: The ASRock RX 7900 XTX Phantom Gaming represents excellent flagship performance with genuine strengths in cooling efficiency and build quality. This is a confident choice for users prioritizing performance and are willing to accommodate the substantial size and power requirements.
Buying Guide: What to Look For in a 24GB GPU for AI
GPU Architecture and Tensor Core Generation
Architecture generation matters more for AI than raw clock speed. The NVIDIA RTX PRO 4000 Blackwell Graphics Card and its compact sibling, the NVIDIA RTX PRO 4000 SFF Blackwell 24GB GDDR7 ECC, are built on NVIDIA’s latest Blackwell architecture with fifth-generation Tensor Cores and PCIe 5.0 connectivity, giving them a decisive edge in matrix operations and AI inference throughput.
Older architectures like the Pascal-based NVIDIA 900-2G610-0000-000 TESLA P40 24GB GDDR5 still deliver solid INT8 throughput at a fraction of the cost, but they lack the Tensor Core density and software ecosystem maturity of newer Ada Lovelace or Blackwell designs. If you are deploying in 2026, prioritize at least Ada Lovelace or RDNA 4 for the best framework compatibility.
Memory Bandwidth and Bus Width
VRAM capacity gets the headlines, but bandwidth is what actually moves data during training and inference. The ASUS Turbo Radeon AI PRO R9700 32GB Graphics Card and the ASRock Radeon AI PRO R9700 Creator 32GB both run a 256-bit bus with up to 640 GB/s bandwidth, which keeps large model layers fed without stalling. Narrower buses, like the 192-bit interface on the ASRock Intel Arc Pro B60 Creator 24GB Graphics, are still workable for inference but can become a bottleneck during heavier training passes.
GDDR7 memory, found on the two RTX PRO 4000 Blackwell cards, also offers a generational leap in raw throughput compared to GDDR6 and GDDR6X. If your workflow involves continuous batched inference or frequent model swapping, that extra bandwidth headroom pays off quickly.
Form Factor and Thermal Design
For multi-GPU builds and rack-mounted workstations, blower-style cooling is the practical choice. The ASRock Radeon AI PRO R9700 Creator 32GB uses a professional blower with a vapor chamber and industrial thermal interface material, exhausting heat directly out of the chassis. That design prevents thermal recirculation when cards are mounted side by side.
If you are building a single-GPU workstation and need something discreet, the SFF Blackwell card is a low-profile dual-slot design that fits into compact chassis without sacrificing performance. The ASRock Radeon RX 7900 XTX Phantom Gaming 24GB OC takes the opposite approach with a triple-fan open-air cooler, which runs quieter in open cases but needs adequate spacing between expansion slots.
Software Ecosystem and Driver Support
CUDA compatibility is still the path of least resistance for most AI frameworks. PyTorch, TensorFlow, and the majority of LLM inference tools like llama.cpp and vLLM have CUDA as their primary target. NVIDIA’s professional drivers also carry ISV certifications that matter for enterprise deployments.
AMD’s ROCm stack has matured considerably, and the RDNA 4 cards now support ROCm 6.x with respectable PyTorch integration. The ASRock Intel Arc Pro B60 Creator 24GB Graphics supports OpenVINO and offers 197 INT8 TOPS with 160 XMX matrix engines, making it a credible alternative for inference-focused workloads where CUDA is not a hard requirement.
Final Thoughts
The 24GB VRAM tier has never offered more variety than it does in 2026, from renewed data center hardware to cutting-edge Blackwell workstation cards. If you need the absolute best professional AI GPU with modern architecture and ECC memory, the NVIDIA RTX PRO 4000 Blackwell Graphics Card is the one to beat. For AI developers who want a strong AMD alternative with generous VRAM headroom and multi-GPU density, the ASRock Radeon AI PRO R9700 Creator 32GB delivers serious throughput with a proven blower thermal solution built for sustained workloads.
Frequently Asked Questions
Is 24GB of VRAM enough for running large language models locally in 2026?
For most practical LLM use cases in 2026, 24GB is a strong starting point. You can comfortably run 7B to 13B parameter models at full precision, and many 30B to 70B models at quantized 4-bit or 8-bit precision. For fine-tuning larger architectures, pairing two 24GB cards in a multi-GPU setup expands your options significantly.
What is the difference between a consumer GPU and a professional workstation GPU for AI?
Professional GPUs like the RTX PRO 4000 Blackwell or RTX 4500 Ada include ECC memory, ISV-certified drivers, and are validated for 24/7 operation under sustained compute loads. Consumer cards such as the RX 7900 XTX offer excellent throughput for their tier but typically lack ECC protection and may not carry enterprise software certifications. For production AI infrastructure, professional cards reduce the risk of silent data corruption during long training runs.
Is a renewed NVIDIA Tesla P40 still worth considering for AI inference?
The NVIDIA 900-2G610-0000-000 TESLA P40 24GB GDDR5 remains a budget-accessible entry point into 24GB AI compute, particularly for INT8 inference workloads where its 47 TOPS throughput is genuinely useful. The Pascal architecture does lack modern Tensor Core generations, which means some newer framework optimizations will not apply. It is best suited for teams with existing CUDA pipelines who need VRAM capacity more than architectural modernity.
Can I use a 24GB gaming GPU like the RX 7900 XTX for AI development?
Yes, and many developers do exactly that. The ASRock Radeon RX 7900 XTX Phantom Gaming 24GB OC has 24GB of GDDR6 on a wide 384-bit bus, which gives it serious memory bandwidth for AI inference and local model experimentation. AMD’s ROCm support has improved enough in 2026 that popular frameworks work reliably. The main tradeoff compared to a workstation card is the lack of ECC memory and the open-air cooler, which is less ideal for enclosed multi-GPU builds.




Write Your Review
No reviews yet. Be the first to share your experience!