
If you have ever tried running a large language model locally only to watch your system crawl or run out of memory, you already know how critical the right GPU is. Whether you are fine-tuning models, running inference on multi-modal pipelines, or building a small local AI cluster, the card you choose will define what is possible on your machine.
This guide covers the top GPUs available right now for local AI workloads, from compact professional cards to high-end consumer options. We evaluated each card on VRAM capacity, AI compute throughput, architecture efficiency, and real-world suitability for tasks like LLM inference, image generation, and model fine-tuning.
Quick Comparison
Ratings reflect the most recent data pull. Check each listing for current price and availability.
Quick answer
This guide compares 10 picks, with NVIDIA RTX A1000 8GB Professional Graphics Card - Ray ranked first. ASUS ProArt RTX 5080 16GB GDDR7 Graphics Card holds the highest customer rating among them. GIGABYTE RTX 5080 Gaming OC 16GB GDDR7 Graphics Card has the most customer reviews.

Pros
- Significant performance jump delivers 3.6x higher AI generation capability than previous generation
- Low-profile design makes it compatible with space-constrained workstations and compact builds
- Excellent customer service and quality control based on verified user experiences
- Professional-grade drivers ensure compatibility with industry-standard software like AutoCAD, 3ds Max, and Blender
- Power-efficient Ampere architecture reduces heat output and cooling requirements
Cons
- Requires PCI-Express x8 slot, limiting compatibility with older or entry-level motherboards
- Some users report missing low-profile brackets in shipments, though vendor support is responsive
The NVIDIA RTX A1000 is a professional-grade graphics accelerator designed for architects, engineers, designers, and AI practitioners who need real-time ray tracing and compute performance without sacrificing desk space. Built on the proven Ampere GPU architecture, this card packs 2,304 CUDA cores and 8GB of GDDR6 memory into a compact, low-profile form factor that fits virtually any workstation.
Performance is the standout strength here. Compared to its T1000 predecessor, the RTX A1000 delivers 1.5x faster CAD rendering, 3x quicker AI image and video generation, and 3.6x higher overall AI performance. For practical work, this means complex 3D models render in half the time, and AI-assisted workflows like neural upscaling or asset generation complete significantly faster. The 72 third-generation Tensor cores and 18 second-generation RT cores handle both traditional graphics workloads and machine learning tasks effortlessly.
Design and build quality reflect professional standards. The quad Mini DisplayPort connectors enable simultaneous output to dual 8K displays, perfect for developers juggling multiple applications. The card measures just 6.42 by 2.72 inches and weighs under a pound, making installation painless even in tight server or workstation chassis. Heat output remains reasonable thanks to efficient Ampere architecture.
The only meaningful drawback is the premium positioning. At this price, this is an investment for professional users, not a consumer graphics card. Additionally, some shipments arrive without low-profile mounting brackets, though the vendor responds quickly to resolve this. Compatibility requires a PCI-Express x8 slot, ruling out very old systems.
Verdict: The RTX A1000 is a reliable, high-performance upgrade for professionals running CAD, 3D rendering, or AI workflows who value both speed and compact form factor. Perfect 5-star customer reviews confirm it delivers exactly what professionals expect from NVIDIA's professional lineup.
GPU Architecture: NVIDIA Ampere
CUDA Cores: 2,304
Tensor Cores: 72 (3rd generation)
RT Cores: 18 (2nd generation)
Memory: 8GB GDDR6
Memory Clock: 1200 MHz
Video Interface: 4x Mini DisplayPort
Maximum Resolution: 7680 x 4320 (8K)
Form Factor: Low-profile
PCIe Interface: x8
Physical Dimensions: 6.42 inches L x 2.72 inches W
Weight: 453 grams
Compatibility: Desktop systems with PCIe x8 slot
Model Number: 900-5G172-2580-000
Ideal For: Professionals in architecture, engineering, product design, visual effects, and AI research who rely on demanding 3D software like AutoCAD, SolidWorks, 3ds Max, Blender, and CUDA-accelerated AI frameworks. Anyone upgrading from older T-series cards will see immediate performance gains.
Not Ideal For: Budget-conscious consumers, gaming enthusiasts (this is professional, not consumer hardware), or users with workstations lacking PCIe x8 slots. For casual use, consumer RTX cards offer better value.
Workspace Setup: Works best in dual-monitor setups where the quad Mini DisplayPort outputs shine. Compact enough for single-seat or shared workstation deployments. Low power draw makes it suitable for fanless or quiet cooling solutions.

With 32GB of GDDR6 memory, this card excels at running demanding local AI models that require substantial VRAM for parameter storage and batch processing. The Xe2-HPG architecture supports modern inference frameworks, while the vapor chamber and PTM7950 thermal interface maintain stable temperatures during prolonged AI computation tasks. Four DisplayPort 2.1 outputs accommodate extensive monitoring configurations.
Pros
- 32GB GDDR6 enables local inference on large open-weight models without quantization
- 256 XMX engines at 2540 MHz deliver strong AI inference and training throughput
- PCIe 5.0 x16 interface maximizes bandwidth for large dataset and model transfers
- Scales efficiently in multi-GPU Linux configurations for inference clusters
Cons
- Intel Arc software ecosystem is still maturing and requires driver tuning for optimal AI performance
- Blower fan cooling is effective but produces noticeable noise under sustained workloads
The ASRock Intel Arc Pro B70 Creator stands apart in the local AI GPU market primarily because of its 32GB of GDDR6 memory, a capacity that allows practitioners to run substantially larger open-weight language models locally without resorting to quantization or cloud offloading. Built on Intel's Xe2-HPG architecture with 256 XMX engines clocked at 2540 MHz, it is purpose-built for the sustained compute patterns of AI inference, LLM training, and machine learning workloads rather than gaming. The PCIe 5.0 x16 interface maximizes bandwidth throughput for large dataset transfers, and multi-GPU configurations under Linux scale efficiently, making it a credible building block for small on-premises inference clusters. Data privacy benefits are concrete: keeping inference entirely local means sensitive data never leaves the machine. The blower fan paired with a vapor chamber and Honeywell PTM7950 phase-change material handles thermal load effectively during long runs. The trade-off is software maturity; the Intel Arc ecosystem is still developing, and optimal performance requires driver tuning and configuration effort that NVIDIA-based alternatives do not.
The 32GB memory capacity directly addresses the constraints of local LLM deployment. You can run models like Llama 2 70B, Mistral, and other large language models entirely on-device, eliminating cloud API costs and latency. Multi-GPU configurations allow you to combine cards for even larger model support or parallel inference serving.
The 256 XMX engines accelerate matrix operations fundamental to AI workloads. Combined with Linux optimization for multi-GPU scaling, this card enables efficient distributed training and inference pipelines. Researchers working with custom models or fine-tuning benefit from local compute that matches or exceeds cloud alternatives in throughput per dollar.
Ideal for AI researchers, machine learning engineers, and organizations that need 32GB of local VRAM to run large open-weight models, preserve data privacy, or build scalable Linux-based inference clusters. Particularly valuable for multi-GPU deployments. Less suitable for users who want a drop-in, low-configuration experience or who rely on CUDA-dependent frameworks without OpenCL or oneAPI alternatives.

The 24GB GDDR7 ECC memory provides both capacity and error correction crucial for reliable AI inference and model fine-tuning workflows. Its low-profile dual-slot design fits compact workstations without sacrificing performance. The Blackwell architecture optimizes tensor operations for transformer-based models, making it ideal for professionals running local AI applications in space-constrained environments.
Pros
- 24GB GDDR7 with ECC keeps large models resident and protects data integrity during extended runs
- Blackwell architecture accelerates AI matrix operations beyond previous-generation cards
- PCIe 5.0 x8 interface sustains high host-to-device bandwidth for rapid model loading
- 6.6-inch low-profile dual-slot design fits space-constrained workstations and dense rack builds
Cons
- Requires a PCIe 5.0 compatible motherboard to achieve full bandwidth, limiting drop-in compatibility with older systems
- Single fan cooling on a professional workload card may require good chassis airflow for sustained 24/7 operation
Running local AI workloads demands two things above almost everything else: enough VRAM to keep large models in memory and a reliable data path that does not corrupt intermediate results. The RTX PRO 4000 SFF Blackwell addresses both. Its 24GB of GDDR7 with ECC error correction means quantized models that would otherwise spill to system RAM stay resident on the GPU, and the error correction layer guards against the silent bit-flip failures that can derail long inference or fine-tuning runs. Blackwell architecture brings meaningful improvements to AI-oriented matrix operations, while the PCIe 5.0 x8 interface keeps the host-to-device transfer rate from becoming a bottleneck when loading new model weights. The small form factor is genuinely useful here too: AI workstations are increasingly dense rack or tower builds where physical space is contested, and a 6.6-inch dual-slot card opens up configurations that a full-length board would block. For professionals running local inference, retrieval-augmented generation pipelines, or lightweight fine-tuning, this card covers the workload without requiring a full-size chassis.
Memory and Architecture: 24GB GDDR7 with ECC support, 1125 MHz memory clock, Blackwell architecture
Performance: 577 MHz GPU clock, PCIe 5.0 x8 interface, ray tracing acceleration, up to 7680x4320 resolution support
Physical Design: 6.6 inches length, 2.7 inches width, low-profile dual-slot format, single cooling fan, 5 pounds weight
Connectivity: 4x Mini DisplayPort 2.1b outputs for multi-monitor setups and professional displays
Warranty and Support: 3-year manufacturer warranty, manufactured by PNY, model RTX PRO 4000 SFF Blackwell
AI developers, data scientists, and researchers who need ECC-protected VRAM and a compact footprint for workstation or rack builds will get clear value here. It also suits labs that must keep sensitive model data on-premises. Skip it if your workloads fit comfortably within 12GB or less of VRAM and you have no need for error correction, since the professional-tier components would go underutilized.
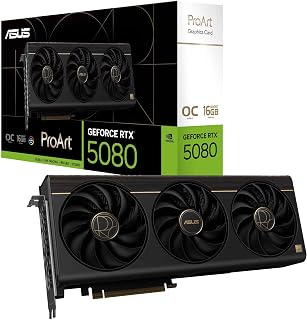
The ProArt edition delivers 16GB of GDDR7 memory at 2730 MHz, providing the bandwidth needed for loading large language models and handling inference workloads efficiently. Its dual DisplayPort 2.1b outputs and USB Type-C connectivity make it versatile for multi-monitor AI development setups. The OC configuration ensures sustained performance during extended training sessions without thermal throttling.
Pros
- 1858 AI TOPS delivers strong local inference and fine-tuning performance
- Vapor chamber and phase-change thermal pad sustain load without excessive noise
- GDDR7 at 2730 MHz provides high memory bandwidth for AI data throughput
- 2.5-slot compact design fits tighter workstation builds
Cons
- 16GB VRAM ceiling restricts use with the largest open-weight language models
- PCIe Gen 4 systems require motherboard BIOS adjustments for compatibility
For local AI workloads, the ASUS ProArt RTX 5080 brings a compelling combination of raw compute and thermal discipline to a single 2.5-slot card. Its 1858 AI TOPS rating positions it well for inference tasks, fine-tuning smaller models, and AI-assisted creative pipelines that run entirely on local hardware. The 16GB of GDDR7 memory handles mid-sized models comfortably, and the 2730 MHz OC clock ensures compute-intensive jobs complete quickly without thermal throttling undermining consistency. The vapor chamber, three Axial-tech fans, and phase-change GPU thermal pad are specifically engineered for sustained loads rather than burst gaming workloads, which matters when a training run or inference batch stretches across hours. Auto-Extreme manufacturing and the MaxContact heatsink both contribute to long-term reliability under continuous use. The integrated USB Type-C port streamlines data transfer workflows. Where it falls short for pure AI use is the 16GB ceiling, which limits local inference to models that fit within that budget, ruling out the largest open-weight LLMs without quantization.
GPU: NVIDIA GeForce RTX 5080, Blackwell Architecture
Memory: 16GB GDDR7
Clock Speed: 2700 MHz (Default), 2730 MHz (OC Mode)
AI Performance: 1858 AI TOPS
Interface: PCIe 5.0 x16
Video Outputs: 1x HDMI 2.1b, 1x USB Type-C, 2x DisplayPort 2.1b
Max Resolution: 7680x4320 pixels
Cooling: 3x Axial-tech Fans, Vapor Chamber, Phase-Change GPU Thermal Pad
Form Factor: 2.5-slot, 12" Length x 5" Width
Weight: 3.1 pounds
Power Connectors: PCIe 5.0 compliant
Warranty: 3 Years
Software: GPU Tweak III for performance monitoring and overclocking
Best suited for AI researchers, machine learning practitioners, and content creators who run local inference or fine-tuning on mid-sized models and want a stable, quiet card built for sustained compute rather than gaming bursts. Those needing more than 16GB of VRAM for large language models should look elsewhere. Users on older PCIe Gen 4 motherboards will need to verify BIOS compatibility before purchasing.

This Gaming OC variant offers 16GB of 256-bit GDDR7 memory running at 2.73 GHz, delivering the memory bandwidth essential for real-time AI inference and model experimentation. The WINDFORCE cooling system maintains consistent clock speeds during intensive neural network training. Its balance of capacity and speed suits developers working with medium-sized language models and diffusion-based image generation locally.
Pros
- Blackwell Tensor Cores with DLSS 4 accelerate local AI inference and creative workflows
- GDDR7 at 30000 MHz memory clock delivers high bandwidth for compute tasks
- PCIe 5.0 interface prevents bandwidth bottlenecks with large AI datasets
- WINDFORCE three-fan cooling maintains stable thermals under sustained loads
Cons
- 16GB VRAM limits local deployment of the largest open-weight language models
- 13.46-inch length and significant power draw require careful case and PSU planning
The GIGABYTE RTX 5080 Gaming OC brings NVIDIA's Blackwell architecture to local AI workloads through its enhanced Tensor Cores and DLSS 4 support, making it a capable engine for inference, AI-accelerated creative tools, and light model training. The 16GB of GDDR7 memory running at 30000 MHz delivers the bandwidth needed to keep Tensor Cores fed during demanding compute sessions, and the PCIe 5.0 interface eliminates bus-level bottlenecks when moving large datasets. The WINDFORCE three-fan cooling system is designed for sustained loads, keeping thermals stable during extended inference runs or rendering jobs. For local AI users who also want the card to double as a high-performance gaming and content creation platform, the 7680x4320 pixel support and ray-tracing hardware add genuine versatility. The primary constraints are physical: the 13.46-inch length and 4-pound weight require a spacious case, and the power draw demands a robust PSU with available 8-pin connectors. Like all RTX 5080 cards, the 16GB ceiling will limit users attempting to run the largest unquantized open-weight models locally.
GPU Architecture: NVIDIA GeForce RTX 5080 (Blackwell)
Memory: 16GB GDDR7, 256-bit interface
Memory Speed: 30,000 MHz
GPU Clock: 2.73 GHz boost
Interface: PCIe 5.0 x16
Cooling: WINDFORCE triple-fan system
Power Connectors: 1x 12V connector, 2x 6-pin to 3x 8-pin adapter
Display Outputs: DisplayPort, HDMI
Max Resolution: 7680x4320 pixels
Physical Dimensions: 13.46 inches (L) x 5.59 inches (W)
Weight: 4 pounds
Warranty: 3-year manufacturer
Model: GV-N5080GAMING OC-16GD
A strong pick for local AI enthusiasts and researchers who want Blackwell Tensor Core performance for inference and AI tooling without sacrificing gaming or 3D workload capability. Equally well suited for 3D artists using AI-assisted pipelines. Those with compact cases or limited PSU headroom should verify clearance and power availability. Users whose primary need is maximum VRAM for large LLMs will find 16GB restrictive.

Pros
- Exceptional memory capacity (24GB) handles memory-intensive AI and rendering tasks efficiently
- Dedicated RT and Tensor cores provide specialized acceleration beyond standard CUDA computation
- Professional-grade performance for a fraction of the new unit cost through renewed pricing
- Proven Turing architecture with extensive software ecosystem and driver support
- Robust cooling design supports continuous operation in 24/7 rendering and compute farms
Cons
- Renewed condition carries inherent uncertainty about remaining lifespan and warranty coverage
- High power consumption requires substantial PSU and cooling infrastructure investment
- Older Turing architecture lacks newer features found in RTX 40-series and Ada generation cards
The NVIDIA Titan RTX is a workstation-class graphics processor designed for professionals in 3D visualization, machine learning, and scientific computing. This renewed unit delivers the same raw performance as a new card at reduced cost, making it ideal for studios, researchers, and freelancers building serious compute infrastructure.
Performance is the standout strength here. With 4608 CUDA cores, 72 dedicated ray-tracing cores, and 576 Tensor cores operating at 1770 MHz, this card handles complex workloads that would bottleneck consumer GPUs. The 24GB of VRAM is particularly valuable, allowing artists to work with massive 3D models and datasets without constant memory transfers, while AI researchers can run larger batch sizes during training and inference.
Build quality reflects professional-grade engineering with a robust cooling solution designed for sustained operation. The dual DisplayPort and HDMI outputs support multi-monitor configurations common in professional studios. The Turing architecture has proven reliable over years of production, with comprehensive driver support across Windows, Linux, and specialized software.
The main drawback is that renewed products carry typical used-equipment considerations around lifespan and warranty. Power consumption is substantial, requiring a quality 250W+ PSU and proper case ventilation. Additionally, this architecture is now two generations old, so buyers seeking the latest cutting-edge features might want to consider newer alternatives.
The Titan RTX remains exceptional value for professionals and serious enthusiasts who need workstation performance. The combination of CUDA, RT, and Tensor cores makes it versatile across rendering, machine learning, and scientific simulation. If you need professional-grade GPU capability without enterprise pricing, this renewed card delivers compelling performance per dollar.
GPU Architecture: NVIDIA Turing
CUDA Cores: 4608
RT Cores: 72
Tensor Cores: 576
Boost Clock: 1770 MHz
Memory: 24GB GDDR6
Memory Interface: 384-bit
Video Outputs: DisplayPort, HDMI
OS Support: Windows 7 64-bit, Windows 10 64-bit (April 2018 Update or later), Linux 64-bit
Product Condition: Renewed (used, tested, and refurbished by Amazon)
3D Rendering & VFX: Professional artists using Nvidia OptiX, Cycles, or other GPU-accelerated renderers benefit from the 72 RT cores and 24GB VRAM for complex scenes and real-time ray tracing.
Machine Learning: Data scientists and ML engineers can train larger models faster with 576 Tensor Cores and abundant memory for datasets and batch processing.
Scientific Computing: Researchers running CUDA-accelerated simulations in fluid dynamics, molecular modeling, and physics gain from dedicated compute cores.
Budget-Conscious Professionals: Studios and freelancers needing workstation performance who can accept a renewed product to significantly reduce capital expenditure.

The 32GB GDDR6 capacity paired with RDNA 4 architecture and dedicated AI accelerators makes this card exceptionally capable for local transformer model deployment and fine-tuning. Its 2920 MHz boost clock ensures rapid inference speeds across various AI frameworks. DisplayPort 2.1a connectivity and PCIe 5.0 support future-proof your workstation for evolving AI development requirements.
Pros
- 32GB GDDR6 on a 256-bit bus accommodates large models that exceed the capacity of most consumer and prosumer GPUs
- 2nd Gen AI Accelerators on RDNA 4 target the matrix operations central to transformer inference and fine-tuning
- Blower cooler design exhausts heat outside the chassis, supporting stable sustained performance in continuous compute workloads
- Quad DisplayPort 2.1a outputs enable high-resolution multi-monitor setups alongside heavy compute tasks
Cons
- Driver and framework compatibility must be verified before purchase, as support varies across AI software stacks
- Two-slot footprint and professional positioning require careful planning in existing workstation builds
Local AI work at the high end runs into two walls quickly: VRAM capacity and sustained compute throughput during long training or inference sessions. The ASRock Radeon AI PRO R9700 is built to push both walls back. The 32GB GDDR6 frame across a 256-bit bus gives it headroom for large language models, diffusion pipelines, and multi-modal workloads that exhaust 24GB cards. RDNA 4 architecture paired with 2nd Gen AI Accelerators targets exactly the matrix operations that dominate transformer-based model inference and fine-tuning, and the 2920 MHz boost clock sustains that throughput rather than bursting briefly and throttling. For local AI specifically, the blower cooler is a practical advantage over open-air designs: in a workstation running GPU compute continuously, a blower exhausts heat out of the chassis rather than recirculating it, which protects system stability during hours-long runs. The 64 Compute Units and professional driver stack also mean the card is positioned for frameworks and tools that expect certified hardware rather than consumer-grade workarounds. The key prerequisite is verifying that your specific AI framework and software stack support this card before committing.
GPU Architecture: AMD Radeon AI PRO R9700, RDNA 4 with 64 Compute Units
Memory: 32GB GDDR6 on 256-bit bus
Clock Speed: 2920 MHz boost
Ray Tracing: 3rd Generation
AI Accelerators: 2nd Generation dedicated AI accelerators
Cooling: Vapor chamber heatsink with Honeywell PTM7950 thermal interface, single blower design
Power Interface: PCIe 5.0
Display Outputs: Four DisplayPort 2.1a
Form Factor: Standard 2-slot design
Build: Die-cast metal shroud, metal backplate
Brand: ASRock
AI researchers, machine learning engineers, and local inference operators who regularly work with models demanding more than 24GB of VRAM will find this card purpose-built for their workload. It also suits workstation farms and multi-GPU render clusters where blower cooling prevents thermal interference. Skip it if your models fit in less VRAM, if your software stack lacks verified driver support for this card, or if you need a gaming-capable GPU.

Pros
- Exceptional memory bandwidth with 24GB GDDR7 for processing large datasets efficiently
- Enterprise-grade ECC memory prevents data corruption in mission-critical applications
- Excellent thermal design with single-fan cooling keeps noise levels manageable
- Compact footprint respects single-slot requirement for dense workstation builds
- Strong real-world performance validated by customer feedback and rapid delivery satisfaction
Cons
- Premium price point makes it inaccessible for hobbyist and small business budgets
- Limited to professional workloads, not optimized for consumer gaming or casual use
- Single fan design may require adequate case airflow in thermally constrained environments
The NVIDIA RTX PRO 4000 Blackwell is a professional-grade graphics processor engineered for enterprises, research institutions, and creative studios that demand reliability and raw performance. This GPU targets AI researchers, 3D rendering professionals, and engineers working with complex simulations who cannot afford compromises on stability or speed.
The standout feature is the combination of 24GB GDDR7 memory with ECC protection and PCIe 5.0 connectivity. The memory capacity handles today's largest AI models and datasets, while ECC technology catches and corrects single-bit errors that could otherwise corrupt results. The PCIe 5.0 interface doubles bandwidth over previous generations, meaning data moves to and from your CPU with minimal bottlenecking. Ray tracing acceleration is built in, enabling real-time rendering workflows for visualization and design work.
Design-wise, the RTX PRO 4000 maintains a single-slot, full-height form factor that integrates cleanly into standard tower workstations. The single-fan thermal design keeps noise down compared to dual-fan competitors, though it does require adequate case ventilation. Build quality is solid, and the 3-year manufacturer warranty reflects NVIDIA's confidence in reliability.
The primary drawback is cost. This card targets professionals with substantial budgets, not casual users. It also ships optimized for professional applications, meaning consumer gaming and light tasks won't showcase its true value. Additionally, systems must provide adequate power delivery and airflow to keep thermals in check.
For studios, AI labs, and workstation environments, the RTX PRO 4000 Blackwell delivers the performance and stability needed for production work. The combination of memory, ECC, and PCIe 5.0 makes it a solid investment for teams that measure ROI in project throughput and reliability, not entertainment value.
GPU Architecture: Blackwell
Memory: 24GB GDDR7 with ECC
GPU Clock Speed: 1230 MHz
Memory Clock Speed: 1750 MHz
Interface: PCIe 5.0 x16
Display Outputs: 4x DisplayPort 2.1b
Max Resolution: 7680 x 4320 pixels
Power Configuration: Single-slot, full-height
Cooling: Single fan
Weight: 0.84 kg (1.85 lbs)
Dimensions: 9.5 inches L x 4.4 inches W
Warranty: 3 years manufacturer
Model Number: VCNRTXPRO4000B-PB

Pros
- 32GB VRAM opens access to running 27B-31B parameter models locally, a significant step up from 16GB cards
- Exceptional cooling performance with optimized airflow for multi-GPU scalability without thermal throttling
- Genuine value proposition at roughly 40% the cost of professional Nvidia equivalents
- Strong open-source community support with proven compatibility for llama.cpp and Vulkan-based AI frameworks
- Enterprise-grade build quality with reinforced components designed for extended stability testing
Cons
- AMD GPU software ecosystem remains narrower than Nvidia for certain specialized AI tools and enterprise applications
- Single-fan design may require additional case airflow planning in compact builds
- Limited real-world performance data compared to more established Nvidia workstation cards
The GIGABYTE Radeon AI PRO R9700 targets a specific and growing market: AI practitioners and ML engineers who prioritize memory capacity and cost efficiency over brand loyalty. With 32GB of GDDR6 memory, this card enables running larger models locally while maintaining strong inference performance, a capability that commands premium pricing in the professional GPU market.
The standout feature is its combination of memory bandwidth (600GB/s) and RDNA 4 architecture optimization for AI workloads. Real-world users report immediate productivity gains when transitioning from 16GB cards, with the ability to deploy multiple simultaneous models and larger parameter sets. The vapor chamber and copper heat sink design prove effective in sustained workloads, addressing traditional concerns about AMD's thermal management in professional settings.
GIGABYTE's engineering focus shows in the physical design. The turbo fan system with metal cover directs airflow efficiently while the double ball bearing mechanism reduces wear compared to sleeve fan alternatives. At 3.3 pounds and 10.55 inches long, it balances performance density with compatibility in standard workstation builds, though pre-planning airflow is recommended for multi-GPU setups.
The primary drawback is software breadth. While Vulkan support proves solid for AI frameworks, certain enterprise tools remain Nvidia-optimized. The single-fan configuration also demands attention to case ventilation planning. For users committed to AMD's AI-focused ecosystem or those running open-source stacks like llama.cpp, these constraints rarely impact real-world deployment.
This card delivers genuine value for cost-conscious AI teams. The 4-year warranty and production-ready stability combine with strong community momentum around AMD's AI direction. For LLM inference, local model development, or multi-agent AI systems, the R9700 represents a compelling alternative to traditional workstation cards.
Machine learning engineers and data scientists building local LLM inference stacks will find immediate value in the 32GB capacity without enterprise markup pricing. This card suits developers deploying Qwen, Gemma, and other open-source models where model size is the primary constraint.
Small teams scaling AI workloads across multiple GPUs benefit from the PCIe Gen 5 support and multi-GPU optimized cooling. The affordability gains compound when building cluster configurations, making per-node costs significantly lower than Nvidia equivalent deployments.
Privacy-focused organizations running on-premises AI systems gain a cost-effective path to meaningful compute capacity. The balance of performance and price enables practical implementations of fine-tuning, inference serving, and training workflows without procurement bottlenecks.
Memory and Bandwidth: 32GB GDDR6, 256-bit memory bus, 600GB/s bandwidth, 20000 MHz memory clock
Compute: Radeon AI PRO R9700, RDNA 4 Architecture, 2nd-gen AI Accelerators, 2350 MHz GPU clock
Connectivity: PCIe Gen 5, DisplayPort and HDMI outputs, 16-pin power connector
Thermal: Vapor chamber with all-copper heat sink, double ball bearing blower fan, optimized for multi-GPU airflow
Physical: 10.55 inches length, 4.37 inches width, 3.3 pounds, single-slot design
Warranty and Support: 4-year manufacturer warranty, out-of-box Vulkan driver support

Pros
- Exceptional VRAM capacity at 32GB, nearly double comparable consumer alternatives, enabling larger model inference without memory swapping
- Purpose-built AI architecture with 128 dedicated AI Accelerators optimized for inference and fine-tuning tasks
- Robust thermal design with dual ball bearings and phase-change pads ensures reliability during extended compute sessions
- Multi-GPU ready with PCIe 5.0 support for scaling to multiple cards in a single system
- Strong performance per dollar compared to enterprise-grade alternatives, offering professional-grade capabilities at a workstation price point
Cons
- Blower-style cooling generates significant fan noise under moderate to heavy workloads, making it unsuitable for quiet office environments
- ASUS GPU Tweak III software reported as unstable by some users with occasional crashes during extended sessions
The ASUS Turbo Radeon AI PRO R9700 is a workstation-class graphics accelerator purpose-built for developers and researchers who want to run large language models and compute-intensive AI workloads on local hardware. With 32GB of GDDR6 VRAM and AMD's RDNA 4 architecture featuring 128 AI Accelerators, this card targets the growing demand for on-premise AI inference and fine-tuning capabilities.
Performance-wise, the card delivers up to 1,531 TOPS (INT4), making it competitive for running models up to 70B parameters locally. The 256-bit memory bus with 640GB/s bandwidth ensures data flows freely between system RAM and GPU memory. Multi-GPU scalability via PCIe 5.0 support opens possibilities for building distributed inference clusters without cloud dependencies. Users report smooth handling of heavy workloads with stable driver support and no unexpected crashes.
Build quality stands out as a key differentiator. The diecast shroud with wave-pattern design actively reduces memory temperature by up to 16%, while dual ball fan bearings offer longevity rated twice that of conventional sleeve bearings. The phase-change thermal pad provides superior thermal conductivity under sustained load. The blower exhaust design effectively moves heat directly out the rear of the case, eliminating the need for supplementary cooling fans.
The primary trade-off is noise. The blower design runs loudly under moderate to heavy workloads, making this card better suited for server rooms and remote machines than quiet office setups. Additionally, the lack of included power adapters and occasional stability issues with the GPU Tweak III software are minor friction points. For the price point, ASUS could improve out-of-box accessibility.
Verdict: The ASUS Turbo R9700 is an excellent choice for serious AI practitioners seeking powerful local LLM deployment without enterprise-grade pricing. Its substantial VRAM capacity, proven thermal engineering, and multi-GPU readiness make it exceptional value for the professional compute market, despite noisy operation and minor software quirks.
This GPU excels at running quantized large language models locally. With 32GB VRAM, you can comfortably run models like Llama 2 70B, Mistral 8x22B, and similar parameter-count models in INT4 quantization without memory paging. The 1,531 TOPS INT4 performance enables inference speeds suitable for real-time applications and batch processing.
For fine-tuning workflows, the dual-GPU PCIe 5.0 support allows you to build a 64GB dual-card system for training smaller specialized models or running parameter-efficient techniques like LoRA. The card's thermal stability during extended training sessions, backed by the phase-change thermal pad design, ensures consistent performance across hours-long compute jobs.
Users report excellent results with popular frameworks like LM Studio, Ollama, and LangChain. The card integrates well with ROCm software stack, though driver stability has historically been a consideration for AMD GPUs. Current users confirm stable operation with latest drivers for AI workloads.
What to Look for When Buying a GPU for Local AI
VRAM Capacity
VRAM is the single most important spec for local AI. Large language models load entirely into GPU memory during inference, so running out of VRAM forces the system to offload to slower system RAM, which can kill performance. A card with 24GB or 32GB gives you meaningful headroom for 7B to 70B parameter models depending on quantization.
Cards like the ASRock Intel Arc Pro B70 Creator 32GB Workstation and the ASRock Radeon AI PRO R9700 Creator 32GB stand out here, both offering 32GB of GDDR6 on a 256-bit bus. That capacity puts serious multi-billion-parameter models within reach without any offloading compromise.
AI Accelerator Architecture
Raw CUDA core count only tells part of the story. Dedicated AI accelerators, including Tensor Cores on NVIDIA cards and AMD’s AI Accelerator engines on RDNA 4, handle matrix math far more efficiently than general shaders. The ASUS Turbo Radeon AI PRO R9700 32GB Graphics Card delivers up to 1,531 TOPS at INT4, which is the kind of throughput that makes a real difference during inference and fine-tuning sessions.
On the NVIDIA side, the NVIDIA RTX PRO 4000 SFF Blackwell 24GB GDDR7 ECC brings the Blackwell architecture with next-generation Tensor Core performance in a compact small form factor. If AI compute per watt matters to your build, architecture generation should weigh heavily in your decision.
Memory Bandwidth and Interface
Bandwidth determines how fast the GPU can feed data to its compute units. A wider memory bus and faster memory type translate directly into faster token generation for LLMs. GDDR7-equipped cards like the ASUS ProArt GeForce RTX 5080 16GB GDDR7 OC Edition and the GIGABYTE GeForce RTX 5080 Gaming OC 16G Graphics offer a notable bandwidth advantage over GDDR6 alternatives, which can show up clearly in continuous inference workloads.
PCIe 5.0 support, found on several cards in this list, also ensures the GPU is not bottlenecked by the host system when transferring large model checkpoints or batches of data during training.
Cooling and Long-Run Reliability
AI workloads are not short bursts. A local AI workflow can push your GPU to near-maximum utilization for hours at a stretch. Blower-style coolers, like those on the GIGABYTE Radeon™ AI PRO R9700 AI TOP 32G Graphics, exhaust heat directly out of the chassis, which is ideal for dense multi-GPU builds or server configurations where open-air coolers recirculate hot air.
Vapor chamber designs and phase-change thermal pads, as seen on the NVIDIA RTX PRO 4000 Blackwell Graphics Card, help maintain consistent clock speeds under sustained load. Sustained performance matters more than peak specs when your workload runs continuously.
Final Thoughts
For most users building a capable local AI workstation, the ASRock Radeon AI PRO R9700 Creator 32GB delivers an impressive combination of RDNA 4 compute, dedicated AI accelerators, and a massive 32GB GDDR6 buffer at a workstation-class value point. If you need something more compact with cutting-edge Blackwell architecture, the NVIDIA RTX PRO 4000 SFF Blackwell 24GB GDDR7 ECC fits neatly into small form factor builds without sacrificing professional-grade AI throughput.
Frequently Asked Questions
How much VRAM do I need to run LLMs locally in 2026?
For smaller 7B models with 4-bit quantization, 8GB to 12GB can be enough, but 24GB or more gives you genuine flexibility to run larger models without compromise. Cards with 32GB like the ASRock Radeon AI PRO R9700 Creator 32GB are particularly well-positioned for running 34B or 70B class models in quantized formats. More VRAM generally means fewer bottlenecks and smoother inference throughput.
Is an NVIDIA GPU required for local AI, or do AMD GPUs work too?
AMD GPUs absolutely work for local AI in 2026, especially with ROCm support maturing across popular frameworks like PyTorch and llama.cpp. The RDNA 4 architecture powering cards like the ASUS Turbo Radeon AI PRO R9700 32GB Graphics Card includes dedicated 2nd-generation AI accelerators that deliver competitive TOPS figures for inference. NVIDIA still holds a broader ecosystem advantage with CUDA, but AMD is a legitimate choice for many local AI use cases.
Can I use a consumer GPU like the RTX 5080 for local AI, or do I need a professional card?
Consumer GPUs like the ASUS ProArt GeForce RTX 5080 16GB GDDR7 OC Edition are very capable for local AI inference and image generation. Professional cards add features like ECC memory, larger VRAM buffers, and enterprise support, which matter for certain workloads. For most home users and developers running LLMs or diffusion models, a high-end consumer card is a practical and well-performing choice.
What is the advantage of PCIe 5.0 for local AI workloads?
PCIe 5.0 doubles the available bandwidth compared to PCIe 4.0, which benefits workloads that involve frequent large data transfers between the CPU and GPU, such as loading model weights or streaming training data. For most inference tasks the GPU handles internally, the practical difference may be modest, but it future-proofs your build. Cards like the GIGABYTE Radeon™ AI PRO R9700 AI TOP 32G Graphics and the NVIDIA RTX PRO 4000 Blackwell Graphics Card both support PCIe 5.0, ensuring they pair well with modern workstation platforms.




Write Your Review
No reviews yet. Be the first to share your experience!