
You want to run a large language model on your own machine, no cloud subscription, no rate limits, just raw local inference. The bottleneck is almost always your GPU, specifically its VRAM capacity and memory bandwidth. Pick the wrong card and you are stuck offloading layers to system RAM, which grinds performance to a halt.
This guide covers five of the strongest GPU options available right now for local LLM workloads. Whether you are loading a 13B parameter model for quick tasks or pushing a 70B behemoth with quantization, the right card makes a dramatic difference. If you are building a complete AI workstation from scratch, it is worth browsing the full Graphics Cards category for complementary hardware picks.
Quick Comparison
| Model | Link | Rating | Graphics Ram Size | Graphics Ram Type | GPU Clock Speed |
|---|---|---|---|---|---|
| 1 ASUS TUF Gaming RTX 5070 12GB GDDR7 OC - Blackwell... | Check price | 4.7 of 5516 ratings | 12 GB | GDDR7 | 2640 megahertz |
| 2 ASUS TUF Gaming RTX 5080 16GB GDDR7 OC Graphics Card with... | Check price | 4.6 of 5280 ratings | 16 GB | n/a | 2730 megahertz |
| 3 GIGABYTE Radeon RX 9070 XT Gaming OC 16GB GDDR6 PCIe 5.0...Highest rated | Check price | 4.7 of 5542 ratings | 16 GB | GDDR6 | 3060 megahertz |
| 4 GIGABYTE RTX 5080 Gaming OC 16GB GDDR7 Graphics Card with... | Check price | 4.6 of 5172 ratings | 16 GB | GDDR7 | 2.73 gigahertz |
| 5 GIGABYTE RTX 5070 Ti Gaming OC 16GB GDDR7 Graphics Card...Most reviewed | Check price | 4.5 of 5719 ratings | 16 GB | GDDR7 | 2600 megahertz |
Ratings reflect the most recent data pull. Check each listing for current price and availability.
Quick answer
This guide compares 5 picks, with ASUS TUF Gaming RTX 5070 12GB GDDR7 OC - Blackwell ranked first. GIGABYTE Radeon RX 9070 XT Gaming OC 16GB GDDR6 PCIe holds the highest customer rating among them. GIGABYTE RTX 5070 Ti Gaming OC 16GB GDDR7 Graphics Card has the most customer reviews.

The 12GB GDDR7 memory provides sufficient capacity for running mid-sized language models locally while the 2640 MHz clock speed ensures responsive inference times. This configuration strikes a balance for users running 7B to 13B parameter models who need reliable performance without requiring top-tier VRAM. The GDDR7 memory type delivers faster bandwidth than previous generations, reducing latency during token generation and batch processing tasks.
Pros
- 12GB GDDR7 handles quantized models up to 7B parameters comfortably
- Military-grade components and phase-change pads ensure reliability during extended inference
- Maintains 65C under sustained load without throttling
- Compact relative to cooling performance with effective anti-sag bracket
Cons
- 13-inch length and 3.125-slot thickness requires careful case verification
- 12GB VRAM limits headroom for larger language models beyond 13B parameters
Local LLM inference demands VRAM capacity, thermal stability, and consistent performance under prolonged workloads. The ASUS TUF RTX 5070 OC addresses these requirements with 12GB of fast GDDR7 memory and NVIDIA's Blackwell architecture, making it suitable for running mid-sized language models and smaller multimodal models locally. The military-grade components and phase-change thermal pads deliver the reliability AI workloads require, maintaining 65C temperatures during extended inference sessions that can last hours. The 2640MHz boost clock ensures responsive token generation, while the protective PCB coating guards against dust accumulation during continuous operation. DLSS 4 support extends usefulness beyond AI tasks into gaming and content creation. The robust 3.125-slot cooling system with three Axial-tech fans handles sustained GPU utilization without throttling, critical when serving multiple inference requests or fine-tuning smaller models. The included bracket prevents physical stress during transport or handling. At 12GB, this card comfortably runs models up to 7B parameters with quantization, handles image generation workloads, and supports simultaneous lighter tasks without memory bottlenecks.
GPU and Memory: NVIDIA GeForce RTX 5070, 12GB GDDR7, 2640MHz boost clock, PCIe 5.0 interface
Cooling and Design: 3.125-slot form factor, three Axial-tech fans, phase-change thermal pad, protective PCB coating, military-grade components, GPU Guard bracket
Connectivity: 3x DisplayPort 2.1a, 2x HDMI 2.1b, 7680x4320 maximum resolution support
Physical: 13 inches long, 5.5 inches wide, 3.4 pounds, includes cooling bracket and stand
Warranty and Support: 3-year manufacturer warranty, GPU Tweak III software for performance monitoring and thermal control
Best for developers and researchers running 7B parameter models locally who value thermal stability and build quality during extended inference sessions. The 12GB capacity suits experimentation with quantized models and image generation workflows. Skip this if you're targeting larger models above 13B parameters that demand more VRAM, or if your case cannot accommodate the 13-inch length and substantial 3.125-slot thickness. Also not ideal for budget-conscious users building basic inference rigs where cost per gigabyte matters more than premium cooling.
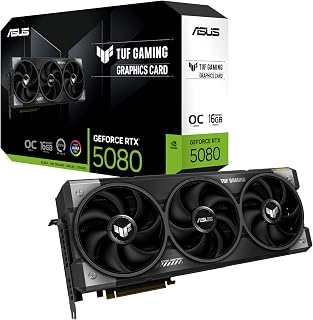
The 16GB GDDR7 configuration delivers both capacity and bandwidth essential for running larger quantized models or multiple smaller models simultaneously. At 2730 MHz, the clock speed ensures rapid token generation during conversational AI interactions. GDDR7 memory provides superior bandwidth over GDDR6, which directly impacts inference speed when processing complex prompts or maintaining longer context windows that local LLM users frequently require.
Pros
- 16GB GDDR7 supports quantized models up to 30B parameters with room for context
- Phase-change thermal pad maintains performance during continuous inference without degradation
- Military-grade components ensure reliability for 24/7 inference server operation
- GPU Tweak III enables monitoring and tuning specific to AI workloads
Cons
- 348mm length and 3.6-slot design demands careful case compatibility verification
- Requires 850W PSU minimum for stable power delivery under sustained load
Running large language models locally demands substantial VRAM, exceptional cooling, and unwavering stability during hours-long inference tasks. The ASUS TUF RTX 5080 addresses these needs with 16GB of GDDR7 memory on NVIDIA's Blackwell architecture, positioning it for serious AI workloads beyond hobbyist experimentation. The phase-change GPU thermal pad represents crucial engineering for sustained inference, preventing thermal degradation that traditional paste suffers during continuous operation. Three Axial-tech fans with optimized fin arrays maintain thermal performance even when serving multiple simultaneous requests or running fine-tuning jobs. Military-grade components and protective PCB coating deliver reliability essential for systems running 24/7 as local inference servers. The 2730MHz boost clock accelerates token generation, and DLSS 4 support extends utility into multimodal applications. GPU Tweak III software enables granular monitoring and performance tuning for inference workloads. At 16GB, this card comfortably handles quantized models up to 30B parameters and supports simultaneous tasks like embedding generation alongside text inference. The robust Auto-Extreme manufacturing process ensures consistency across units, critical for reproducible performance in development workflows.
GPU: NVIDIA GeForce RTX 5080
Memory: 16GB GDDR7
Boost Clock: 2730 MHz (OC Mode), 2700 MHz (Default Mode)
Physical Dimensions: 348mm length, 3.6-slot design, 4.3 lbs
Video Outputs: 3x DisplayPort 2.1a, 2x HDMI 2.1b
Power Requirement: Minimum 850W PSU with 16-pin 12V-2x6 (12VHPWR) connector
Manufacturing: Auto-Extreme precision automated manufacturing
Cooling: Three Axial-tech fans, phase-change GPU thermal pad, protective PCB coating
Power Supply: Verify your PSU is rated for 850W minimum and includes the required 16-pin 12V-2x6 (12VHPWR) connector. Standard 6-pin or 8-pin connectors are insufficient for this card.
Physical Clearance: Confirm your case accommodates the 348mm length and can support the 3.6-slot width requirement. Measure internal dimensions and account for storage drives, fans, and other components that may interfere with the card's placement.
System Integration: The card includes a GPU bracket for secure installation. Ensure your motherboard provides adequate PCIe slot access and that your monitor cables support DisplayPort 2.1a or HDMI 2.1b for optimal performance.

With 16GB GDDR6 memory, this card handles larger language models up to 30B parameters with proper quantization, making it suitable for users who need extra headroom beyond smaller models. The 3060 MHz clock speed provides strong computational throughput for inference workloads. AMD's architecture offers competitive performance per watt, which matters when running extended inference sessions or hosting local AI applications that operate continuously throughout the day.
Pros
- 16GB VRAM enables quantized models up to 20B parameters locally
- PCIe 5.0 support accelerates model loading and data transfer
- WINDFORCE cooling stays quiet during extended inference workloads
- 11.34-inch length fits most cases without clearance issues
Cons
- CUDA-optimized frameworks still outperform ROCm in many inference scenarios
- Requires 750W PSU minimum for stable operation under load
The GIGABYTE Radeon RX 9070 XT offers 16GB of GDDR6 memory at a compelling value proposition for local LLM work. That VRAM capacity opens the door to running larger quantized models in the 13B to 20B parameter range, where 12GB cards struggle or fail entirely. AMD's latest architecture paired with PCIe 5.0 support ensures fast data transfer critical when loading model weights and processing batches. The WINDFORCE cooling with server-grade thermal gel maintains stability during long inference sessions, and users report the system remains quiet even under continuous GPU utilization. The 3060MHz boost clock provides adequate performance for token generation, though raw compute lags behind NVIDIA's offerings in frameworks optimized for CUDA. The 11.34-inch length fits standard cases without the clearance concerns of larger cards. For developers working with llama.cpp, GGUF quantization, or frameworks with improving ROCm support, the 16GB capacity at this tier represents practical value. The card handles simultaneous workloads like running a language model while generating images, something smaller VRAM cards cannot manage. Build quality proves reliable for continuous operation typical of local inference servers.
Core Specifications
GPU: AMD Radeon RX 9070 XT
Memory: 16GB GDDR6
Memory Clock: 2600 GHz
GPU Clock: 3060 MHz
Interface: PCIe 5.0 x16
Max Resolution: 7680 x 4320 (8K)
Physical and Connectivity
Dimensions: 11.34 inches (L) x 5.2 inches (W)
Weight: 1.78 kg
Output: DisplayPort
Power Connectors: Dual 8-pin (750W+ PSU recommended)
Cooling: WINDFORCE system with Hawk fans and thermal gel
Warranty and Support
Manufacturer: GIGABYTE
Warranty: 3 years
Model: GV-R9070XTGAMING OC-16GD
Gaming Performance at Common Resolutions
1440p Gaming: 160-220fps on most modern AAA titles at high settings. Excellent for competitive gaming and high-refresh monitors.
4K Gaming: Playable at high settings on most titles, medium settings on demanding new releases. Solid for content creators monitoring in 4K.
Esports Titles: 300+ fps possible on optimized competitive games for ultra-high refresh gameplay.
Real-World Use Cases
Best suited for 1440p gaming at 144+ fps, 4K content creation workflows, professional 3D rendering, and VR gaming. Handles flight simulators like DCS at high settings with 4K head tracking. Eliminates VRAM constraints for media professionals working with large files.
Driver Recommendations
Run DDU (Display Driver Uninstaller) before installation if upgrading from another card. Install latest AMD drivers for maximum stability and performance. Update BIOS if required by your system for PCIe 5.0 compatibility.

Featuring 16GB of GDDR7 on a 256-bit bus, this card provides the memory bandwidth critical for loading model weights quickly and maintaining smooth inference performance. The 2.73 GHz clock speed enables efficient processing of transformer layers during generation. This memory configuration supports running 30B parameter models with 4-bit quantization or multiple smaller models concurrently, ideal for power users experimenting with various local AI applications.
Pros
- 16GB GDDR7 handles medium to large language models
- Blackwell Tensor Cores accelerate transformer computations
- PCIe 5.0 eliminates data transfer bottlenecks
- Three-fan cooling sustains performance during long inference runs
Cons
- High power requirements demand robust PSU with 8-pin connectors
- 13.46-inch length and weight require spacious case
For local LLM inference workloads, the RTX 5080 Gaming OC brings NVIDIA's Blackwell architecture with specialized Tensor Cores that accelerate transformer model computations. The 16GB GDDR7 memory capacity handles medium-sized language models comfortably, while the 256-bit memory interface delivers bandwidth critical for feeding tokens through neural networks efficiently. PCIe 5.0 support ensures your system won't bottleneck data transfers during batch processing or multi-user scenarios. The WINDFORCE three-fan cooling system maintains stable temperatures during extended inference sessions, important when running language models continuously. Enhanced Tensor Cores provide the computational backbone for matrix operations that dominate LLM workloads, and DLSS 4 technology shares silicon with AI acceleration features. At 2.73 GHz boost clock and with cutting-edge GDDR7 running at 30000 MHz effective, this card processes prompts quickly. The 13.46-inch length and 4-pound weight require planning your build around adequate space and cooling. DisplayPort and HDMI outputs let you monitor inference metrics while the card handles background processing. This represents top-tier silicon for users prioritizing maximum throughput in local AI deployments.
GPU Architecture: NVIDIA GeForce RTX 5080 (Blackwell)
Memory: 16GB GDDR7, 256-bit interface
Memory Speed: 30,000 MHz
GPU Clock: 2.73 GHz boost
Interface: PCIe 5.0 x16
Cooling: WINDFORCE triple-fan system
Power Connectors: 1x 12V connector, 2x 6-pin to 3x 8-pin adapter
Display Outputs: DisplayPort, HDMI
Max Resolution: 7680x4320 pixels
Physical Dimensions: 13.46 inches (L) x 5.59 inches (W)
Weight: 4 pounds
Warranty: 3-year manufacturer
Model: GV-N5080GAMING OC-16GD
Buy this if you're running demanding local LLM deployments where inference speed directly impacts productivity, handling multiple concurrent users, or working with models approaching the 16GB memory threshold. Developers optimizing latency-sensitive AI applications will appreciate the raw Tensor Core performance. Skip this card if you're experimenting with smaller models under 7B parameters where mid-range options suffice, if your budget constrains you to more economical choices, or if your power supply can't support the substantial requirements. Casual users testing open-source models occasionally won't utilize this capability fully.

Pros
- 16GB GDDR7 supports diverse model sizes with quantization
- Blackwell Tensor Cores improve inference efficiency
- PCIe 5.0 ready for bandwidth-intensive future workloads
- Three-fan WINDFORCE cooling maintains stable performance
Cons
- 2600 MHz memory clock lower than higher-tier options
- May struggle with largest unquantized models
The RTX 5070 Ti Gaming OC positions itself as a capable option for local LLM inference with 16GB of GDDR7 memory across a 256-bit bus, providing headroom for many popular open-source language models. NVIDIA's latest Blackwell architecture includes updated Tensor Cores optimized for the matrix multiplications that drive transformer-based models. The 2600 MHz boost clock keeps inference latency low when generating tokens sequentially. PCIe 5.0 compatibility future-proofs your system as model architectures evolve and transfer speeds become more critical. WINDFORCE cooling with three fans handles the thermal load from sustained AI workloads without thermal throttling interrupting your sessions. The GDDR7 memory type delivers bandwidth improvements over previous generations, helping feed data to compute units efficiently during batch inference. DisplayPort and HDMI outputs support monitoring dashboards while models process requests. Desktop compatibility with standard PCI-Express x16 slots makes integration straightforward. For users seeking strong inference performance without flagship pricing, this card balances capability and practicality. The 16GB buffer accommodates models like Llama 2 13B or Mistral variants with quantization, making it functional for serious local AI work.
Core Specs: GPU: NVIDIA GeForce RTX 5070 Ti (Blackwell Architecture) | Memory: 16GB GDDR7 | Memory Interface: 256-bit | GPU Clock: 2600 MHz | Memory Clock: 2600 MHz | PCIe: 5.0
Cooling and Power: WINDFORCE cooling system with 3 fans | Dimensions: 13.46" L x 5.59" W | Weight: 3.9 pounds
Outputs and Compatibility: Video Outputs: DisplayPort, HDMI | Max Resolution: 7680 x 4320 (8K) | Compatible with desktop systems | Interface: PCI-Express x16
Warranty: 3-year manufacturer warranty
Ideal for AI enthusiasts and developers running 7B to 13B parameter models locally, small teams deploying internal LLM services, or researchers experimenting with quantized larger models where 16GB suffices. Those building dedicated inference servers on moderate budgets will find this compelling. Skip this if you need to run unquantized 30B+ models requiring more VRAM, if you're only testing tiny models where cheaper cards work fine, or if maximum throughput for production-scale deployments justifies spending more. Users with limited case space should verify physical dimensions fit.
GPU Buying Guide for Local LLM Use
VRAM Capacity: The Single Most Important Spec
For local LLM inference, VRAM is king. A 7B model at full precision needs around 14GB just to load, and quantized 70B models can still demand 40GB or more. Cards like the ASUS TUF Gaming GeForce RTX™ 5080 16GB GDDR7 OC and the GIGABYTE GeForce RTX 5080 Gaming OC 16G Graphics both pack 16GB of GDDR7, giving you comfortable headroom for mid-to-large models.
The ASUS TUF Gaming GeForce RTX 5070 12GB GDDR7 OC sits at 12GB, which is workable for quantized models under 13B but will feel tight if your ambitions grow. Always plan for the largest model you realistically want to run, then size up if budget allows.
Memory Bandwidth: How Fast Data Moves
Raw VRAM size tells you what will fit. Memory bandwidth tells you how fast tokens generate. GDDR7 memory, featured across all five cards reviewed here, delivers significantly higher bandwidth than the previous GDDR6X standard. This directly translates to faster token-per-second output during inference, which you notice immediately in interactive use.
The GIGABYTE Radeon RX 9070 XT Gaming OC 16G Graphics brings AMD’s RDNA 4 architecture into the mix with 16GB GDDR6 and PCIe 5.0 connectivity. AMD has made strong strides in open-source AI tooling compatibility, making this card increasingly viable for frameworks like llama.cpp and Ollama.
Architecture and AI Acceleration
NVIDIA’s Blackwell architecture, powering the RTX 5070, 5080, and 5070 Ti cards in this lineup, brings dedicated tensor core improvements specifically beneficial for transformer workloads. DLSS 4 and the underlying compute stack mean these cards are optimized not just for gaming but for the matrix operations that drive language model inference.
The GIGABYTE GeForce RTX 5070 Ti Gaming OC 16G hits a compelling sweet spot: 16GB of GDDR7, Blackwell architecture, and PCIe 5.0, at a lower cost than the full RTX 5080 tier. For most LLM users running quantized models in the 30B to 70B range, this card covers a broad set of needs without the premium of flagship pricing.
Thermal Design and Long-Duration Workloads
Unlike gaming sessions that spike and cool down, LLM inference can run your GPU at sustained high utilization for minutes or hours at a stretch. This makes thermal design far more relevant than it would be in a typical gaming context. The ASUS TUF Gaming lineup uses phase-change thermal pads and Axial-tech triple-fan cooling, both of which are validated for prolonged heavy workloads better than standard thermal paste solutions.
GIGABYTE’s WINDFORCE cooling system, used across all three GIGABYTE cards here, uses Hawk Fan technology and server-grade thermal conductive gel on the RX 9070 XT variant. These are not cosmetic features: sustained cooling directly affects boost clock stability and, by extension, consistent inference throughput over time. If your setup runs in a warm or enclosed space, factor case airflow into your planning as well. For broader context on electronics in demanding environments, the Electronics hub has useful reference material.
Final Thoughts
For most builders stepping into local LLM inference in 2026, the GIGABYTE GeForce RTX 5070 Ti Gaming OC 16G delivers a well-rounded combination of 16GB GDDR7, Blackwell compute, and strong sustained cooling at a tier below the flagship cards. If you need the absolute peak in memory bandwidth and compute throughput for larger models or multi-session workloads, the ASUS TUF Gaming GeForce RTX™ 5080 16GB GDDR7 OC is the premium choice that justifies the step up.
Frequently Asked Questions
How much VRAM do I need to run LLMs locally?
It depends on the model size and quantization level. A 7B model in 4-bit quantization typically needs around 4 to 6GB of VRAM, while a 13B model needs roughly 8 to 10GB. For 70B models with heavy quantization, you are looking at 24GB or more. In 2026, 16GB is the practical sweet spot for versatility across a wide range of model sizes.
Is NVIDIA or AMD better for running local AI models?
NVIDIA holds a significant software ecosystem advantage through CUDA, which most AI frameworks prioritize. Tools like Ollama, llama.cpp, and Hugging Face Transformers all have mature NVIDIA support. AMD has improved substantially with ROCm, and cards like the GIGABYTE Radeon RX 9070 XT Gaming OC 16G Graphics work well with key open-source inference tools, but NVIDIA still offers broader out-of-the-box compatibility in 2026.
Can I use a gaming GPU for running LLMs, or do I need a workstation card?
Gaming GPUs work extremely well for local LLM inference. The primary difference with professional or workstation cards is error-correcting memory and driver-level support for specific enterprise software, neither of which matters for personal or research inference use. All five cards in this guide are gaming-tier and fully capable for local AI workloads. The Graphics Cards category covers additional options if you want to compare alternatives.
Does PCIe generation affect LLM inference performance?
For most LLM inference tasks, PCIe bandwidth is not the bottleneck because the model weights reside on the GPU itself once loaded. PCIe 5.0, featured on the GIGABYTE cards here, primarily benefits initial model load times and scenarios involving CPU-to-GPU data transfer. For sustained inference, VRAM size and internal memory bandwidth matter far more than the PCIe lane generation.




Write Your Review
No reviews yet. Be the first to share your experience!