
You fire up Ollama, load a 13B parameter model, and watch your system crawl. Token generation drops to a trickle, your CPU fans scream, and the experience is anything but usable. The bottleneck almost always comes down to one thing: your GPU, specifically how much VRAM it has and how fast it can move data. Picking the right card transforms Ollama from a frustrating experiment into a genuinely powerful local AI setup.
This guide covers six of the strongest GPU options available right now for running Ollama and other local LLM workloads. Whether you want a budget-conscious entry point or a flagship card that handles the largest open-source models without breaking a sweat, there is an option here for you. If you are also browsing other electronics for your build, check out the Electronics category for more gear recommendations.
Quick Comparison
| Model | Link | Rating | Graphics Ram Size | Graphics Ram Type | GPU Clock Speed |
|---|---|---|---|---|---|
| 1 ASUS TUF Gaming RTX 5070 12GB GDDR7 OC - Blackwell... | Check price | 4.7 of 5516 ratings | 12 GB | GDDR7 | 2640 megahertz |
| 2 ASUS TUF Gaming RTX 5080 16GB GDDR7 OC Graphics Card with... | Check price | 4.6 of 5280 ratings | 16 GB | n/a | 2730 megahertz |
| 3 HP NVIDIA Tesla M60 16GB GDDR5 GPU Server Accelerator... | Check price | 4.6 of 53 ratings | 16 GB | GDDR5 | n/a |
| 4 GIGABYTE Radeon RX 9070 XT Gaming OC 16GB GDDR6 PCIe 5.0...Highest rated | Check price | 4.7 of 5542 ratings | 16 GB | GDDR6 | 3060 megahertz |
| 5 GIGABYTE RTX 5080 Gaming OC 16GB GDDR7 Graphics Card with... | Check price | 4.6 of 5172 ratings | 16 GB | GDDR7 | 2.73 gigahertz |
| 6 GIGABYTE RTX 5070 Ti Gaming OC 16GB GDDR7 Graphics Card...Most reviewed | Check price | 4.5 of 5719 ratings | 16 GB | GDDR7 | 2600 megahertz |
Ratings reflect the most recent data pull. Check each listing for current price and availability.
Quick answer
This guide compares 6 picks, with ASUS TUF Gaming RTX 5070 12GB GDDR7 OC - Blackwell ranked first. GIGABYTE Radeon RX 9070 XT Gaming OC 16GB GDDR6 PCIe holds the highest customer rating among them. GIGABYTE RTX 5070 Ti Gaming OC 16GB GDDR7 Graphics Card has the most customer reviews.

The 12GB GDDR7 memory provides adequate capacity for running medium-sized language models locally through Ollama, while the 2640 MHz clock speed ensures responsive inference times. This configuration strikes a balance for users who want to experiment with models like Llama 2 13B or Mistral 7B without requiring the highest-end hardware. The GDDR7 memory type offers faster bandwidth than previous generations, reducing bottlenecks when loading model weights and processing token generation.
Pros
- 12GB GDDR7 handles 13B models with large contexts
- Exceptional cooling maintains 65C during sustained inference
- Military-grade build ensures 24/7 operational stability
- Blackwell architecture optimized for AI acceleration
Cons
- 13-inch length requires spacious case clearance
- 12GB VRAM limits largest model parameters
Running large language models locally through Ollama demands substantial VRAM and sustained compute without thermal throttling. The ASUS TUF RTX 5070 OC delivers 12GB of fast GDDR7 memory on NVIDIA's Blackwell architecture, providing the headroom needed for 7B to 13B parameter models with comfortable context windows. The 2640MHz boost clock accelerates inference speed, while the robust three-fan Axial-tech cooling system maintains 65C under continuous AI workloads where many cards struggle. Military-grade components and phase-change thermal pads ensure stability during hours-long generation tasks. The protective PCB coating and included anti-sag bracket address long-term reliability concerns for systems running 24/7. DLSS 4 support and the card's AI acceleration capabilities make it equally capable for image generation models alongside text inference. The 3.125-slot design prioritizes thermal performance over compact dimensions, a worthy trade for users serious about local AI deployment. At 13 inches, case compatibility requires verification, but the engineering focus on sustained performance rather than burst benchmarks aligns perfectly with Ollama's compute profile.
GPU and Memory: NVIDIA GeForce RTX 5070, 12GB GDDR7, 2640MHz boost clock, PCIe 5.0 interface
Cooling and Design: 3.125-slot form factor, three Axial-tech fans, phase-change thermal pad, protective PCB coating, military-grade components, GPU Guard bracket
Connectivity: 3x DisplayPort 2.1a, 2x HDMI 2.1b, 7680x4320 maximum resolution support
Physical: 13 inches long, 5.5 inches wide, 3.4 pounds, includes cooling bracket and stand
Warranty and Support: 3-year manufacturer warranty, GPU Tweak III software for performance monitoring and thermal control
Ideal for enthusiasts running multiple concurrent Ollama models, developers testing 13B parameter LLMs locally, or anyone building a dedicated AI workstation where reliability matters as much as performance. The 3-year warranty and enterprise-grade components justify the investment for serious use. Skip this if you're experimenting with smaller 7B models only, working in compact cases under 14 inches, or need 16GB+ VRAM for massive context windows or fine-tuning workloads beyond pure inference.
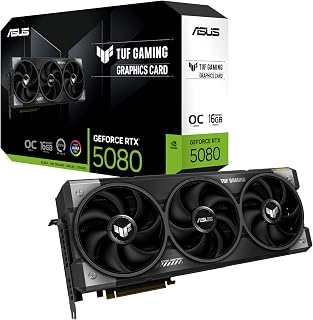
The 16GB GDDR7 configuration delivers both the capacity and bandwidth needed for running demanding language models locally. The 2730 MHz clock speed accelerates inference, reducing wait times when generating responses through Ollama. This memory allocation comfortably handles 13B parameter models and smaller 30B models with quantization, making it suitable for enthusiasts who want to experiment with diverse model architectures without constantly managing VRAM constraints during testing sessions.
Pros
- 16GB GDDR7 handles large parameter models
- Phase-change thermal pad maintains performance in long inference runs
- Tensor Cores accelerate transformer operations
- Military-grade components ensure reliability for continuous operation
Cons
- 850W PSU minimum and 3.6-slot design require compatible chassis
- Flagship positioning increases cost per VRAM gigabyte
Running large language models locally through Ollama demands substantial VRAM and sustained thermal performance, both areas where this ASUS TUF card excels. The 16GB GDDR7 memory provides headroom for loading multi-billion parameter models without running into allocation errors that plague smaller cards. NVIDIA's Blackwell architecture with enhanced Tensor Cores accelerates the matrix operations at the heart of transformer inference, delivering faster token generation compared to previous generations. The phase-change thermal pad technology solves a critical challenge for local AI workloads: maintaining consistent performance during extended inference sessions that can run for hours. Traditional thermal solutions degrade over time, but this implementation keeps temperatures stable even when processing lengthy conversations or batch operations. The three Axial-tech fans and optimized fin array dissipate heat efficiently in extended runs. Military-grade components and protective PCB coating add reliability for systems that operate continuously. GPU Tweak III software allows monitoring of VRAM usage and thermals during model loading. The 850W PSU requirement and 348mm length with 3.6-slot footprint demand careful system planning, but users building dedicated AI workstations will appreciate the robust construction and Auto-Extreme manufacturing quality that ensure long-term stability for production inference workloads.
GPU: NVIDIA GeForce RTX 5080
Memory: 16GB GDDR7
Boost Clock: 2730 MHz (OC Mode), 2700 MHz (Default Mode)
Physical Dimensions: 348mm length, 3.6-slot design, 4.3 lbs
Video Outputs: 3x DisplayPort 2.1a, 2x HDMI 2.1b
Power Requirement: Minimum 850W PSU with 16-pin 12V-2x6 (12VHPWR) connector
Manufacturing: Auto-Extreme precision automated manufacturing
Cooling: Three Axial-tech fans, phase-change GPU thermal pad, protective PCB coating
Power Supply: Verify your PSU is rated for 850W minimum and includes the required 16-pin 12V-2x6 (12VHPWR) connector. Standard 6-pin or 8-pin connectors are insufficient for this card.
Physical Clearance: Confirm your case accommodates the 348mm length and can support the 3.6-slot width requirement. Measure internal dimensions and account for storage drives, fans, and other components that may interfere with the card's placement.
System Integration: The card includes a GPU bracket for secure installation. Ensure your motherboard provides adequate PCIe slot access and that your monitor cables support DisplayPort 2.1a or HDMI 2.1b for optimal performance.

The 16GB memory capacity enables deployment of substantial language models through Ollama, particularly for users building dedicated AI servers. The Tesla architecture was designed specifically for compute-intensive workloads rather than gaming, making it well-suited for continuous inference tasks. While the GDDR5 memory represents older technology, the generous 16GB allocation still accommodates many popular models, and the server-grade design ensures reliability for extended operation periods that home AI setups demand.
Pros
- 16GB GDDR5 VRAM provides generous headroom for large quantized models in Ollama
- Tesla architecture designed for sustained 24/7 compute workloads, not burst gaming loads
- PCI-Express x16 interface is compatible with standard desktop motherboards
- Renewed status includes professional inspection and testing for reliable functionality
Cons
- Card length is notably large and may not fit in standard or compact PC cases without clearance verification
- Tesla architecture lacks consumer driver features and may require additional configuration effort compared to GeForce or Radeon cards
Running Ollama locally demands one thing above all else: enough VRAM to load models without falling back to CPU layers. The HP NVIDIA Tesla M60 delivers exactly that with 16GB of GDDR5 memory, giving you headroom to run 13B parameter models comfortably and push into larger quantized models without constant memory thrashing. Built on NVIDIA's Tesla architecture, this card was engineered for sustained parallel workloads in data centers, which maps well to the continuous inference demands Ollama places on hardware. The 1GHz memory clock keeps token generation moving at a reasonable pace, and the PCI-Express x16 interface slots into any standard desktop motherboard. Because this is a renewed enterprise unit, it has passed professional inspection, making it a pragmatic path to serious VRAM capacity. The professional thermal design handles extended Ollama sessions without throttling, a real advantage over consumer cards not built for round-the-clock compute. Just verify your case has the clearance for this card's length before ordering.
Core Specifications: Graphics Processor: NVIDIA Tesla M60, Graphics Memory: 16GB GDDR5, Memory Clock: 1 GHz, Interface: PCI-Express x16, Compatible Devices: Desktop/Server.
Physical: Brand: HP (Manufacturer: Hewlett Packard Enterprise), Model: NVIDIA Tesla M60, HP Part Number: M3X68A-cr, UPC: 786513494061, Weight: 2 pounds.
Warranty and Support: 90-day limited warranty included. Amazon Renewed Guarantee covers replacement or refund if not satisfied. Product is professionally inspected and tested by Amazon-qualified suppliers.

With 16GB of VRAM, this card accommodates larger language models that Ollama users frequently deploy, including 13B parameter models with headroom for extended context windows. The AMD Radeon architecture provides strong compute performance for inference workloads at a 3060 MHz clock speed. The 16GB capacity becomes critical when running multiple models simultaneously or experimenting with fine-tuned variants that demand additional memory overhead beyond base model requirements.
Pros
- 16GB capacity handles multiple models simultaneously
- Professional thermal design for continuous operation
- Renewed pricing provides enterprise reliability affordably
- Tesla architecture stable for sustained inference workloads
Cons
- Exceptionally long card requires chassis compatibility verification
- Older GDDR5 memory slower than current generation
For budget-conscious developers building Ollama inference servers, the Tesla M60 offers an unconventional path to 16GB VRAM at enterprise reliability standards. This renewed professional accelerator was engineered for 24/7 data center operation, making it naturally suited for always-on local LLM deployments where consumer cards often fall short. The 16GB GDDR5 memory across dual GPUs handles 13B models comfortably and provides enough capacity for multiple smaller models simultaneously. While the 1GHz memory clock won't set speed records, sustained inference throughput remains consistent without thermal throttling thanks to professional-grade cooling designed for continuous compute loads. PCI-Express x16 integration works seamlessly in standard motherboards, and Tesla architecture includes optimizations for parallel processing that benefit transformer model inference. The renewed status delivers professional GPU capabilities without new enterprise pricing, appealing for homelab and small business deployments. HP's enterprise manufacturing standards ensure robust component selection built for longevity rather than marketing aesthetics. This represents a fundamentally different value proposition from gaming-focused cards: prioritizing capacity, stability, and cost-efficiency over peak performance.
Core Specifications
GPU: AMD Radeon RX 9070 XT
Memory: 16GB GDDR6
Memory Clock: 2600 GHz
GPU Clock: 3060 MHz
Interface: PCIe 5.0 x16
Max Resolution: 7680 x 4320 (8K)
Physical and Connectivity
Dimensions: 11.34 inches (L) x 5.2 inches (W)
Weight: 1.78 kg
Output: DisplayPort
Power Connectors: Dual 8-pin (750W+ PSU recommended)
Cooling: WINDFORCE system with Hawk fans and thermal gel
Warranty and Support
Manufacturer: GIGABYTE
Warranty: 3 years
Model: GV-R9070XTGAMING OC-16GD
Gaming Performance at Common Resolutions
1440p Gaming: 160-220fps on most modern AAA titles at high settings. Excellent for competitive gaming and high-refresh monitors.
4K Gaming: Playable at high settings on most titles, medium settings on demanding new releases. Solid for content creators monitoring in 4K.
Esports Titles: 300+ fps possible on optimized competitive games for ultra-high refresh gameplay.
Real-World Use Cases
Best suited for 1440p gaming at 144+ fps, 4K content creation workflows, professional 3D rendering, and VR gaming. Handles flight simulators like DCS at high settings with 4K head tracking. Eliminates VRAM constraints for media professionals working with large files.
Driver Recommendations
Run DDU (Display Driver Uninstaller) before installation if upgrading from another card. Install latest AMD drivers for maximum stability and performance. Update BIOS if required by your system for PCIe 5.0 compatibility.

The 16GB GDDR7 memory provides substantial headroom for Ollama deployments, supporting larger language models and extended context lengths that smaller cards cannot handle. The 2.73 GHz clock speed ensures fast token generation, critical for maintaining responsive local AI interactions. The 256-bit memory interface maximizes bandwidth utilization when loading model weights and processing inference requests, preventing memory transfer speeds from becoming a bottleneck during intensive generation tasks.
Pros
- 16GB GDDR7 accommodates large language models
- Enhanced Tensor Cores accelerate inference operations
- PCIe 5.0 speeds model loading from storage
- WINDFORCE cooling maintains stability in sustained workloads
Cons
- Substantial power requirements need robust PSU infrastructure
- Physical dimensions and weight demand proper case support
Local AI inference through Ollama relies heavily on VRAM capacity and compute throughput, making the 16GB GDDR7 configuration and enhanced Tensor Cores on this GIGABYTE card particularly relevant. Loading models in the 30B to 70B parameter range requires substantial memory bandwidth, which the 256-bit bus and 30000 MHz memory clock deliver efficiently. The Blackwell architecture brings architectural improvements to Tensor Core design that directly accelerate the matrix multiplications central to language model inference, producing tokens faster than older RTX generations. PCIe 5.0 bandwidth eliminates bottlenecks when transferring model weights from system storage into VRAM during initialization. The WINDFORCE triple-fan cooling system maintains thermal stability during prolonged inference workloads where sustained compute loads can stress lesser cooling solutions. DLSS 4 support, while primarily gaming-focused, shares underlying Tensor Core optimizations that benefit AI workloads. The 7680x4320 pixel support matters less for headless AI servers but indicates the card's professional-grade output capabilities. At 4 pounds and 13.46 inches, physical integration requires attention, and the included VGA holder provides necessary support. Robust construction handles continuous operation typical of local AI deployments where models remain loaded in VRAM for rapid query response.
GPU Architecture: NVIDIA GeForce RTX 5080 (Blackwell)
Memory: 16GB GDDR7, 256-bit interface
Memory Speed: 30,000 MHz
GPU Clock: 2.73 GHz boost
Interface: PCIe 5.0 x16
Cooling: WINDFORCE triple-fan system
Power Connectors: 1x 12V connector, 2x 6-pin to 3x 8-pin adapter
Display Outputs: DisplayPort, HDMI
Max Resolution: 7680x4320 pixels
Physical Dimensions: 13.46 inches (L) x 5.59 inches (W)
Weight: 4 pounds
Warranty: 3-year manufacturer
Model: GV-N5080GAMING OC-16GD
Best suited for developers and researchers building local AI infrastructure who need maximum VRAM and compute power for running cutting-edge open-source models. The 16GB capacity and Tensor Core performance justify the investment for users regularly working with 30B+ parameter models or batch processing tasks. Skip this if your Ollama usage centers on smaller 7B-13B models that fit comfortably on mid-range cards, or if your system lacks adequate PSU capacity with available 8-pin connectors and proper case airflow to handle the thermal output.

With 16GB of GDDR7 memory, this configuration supports substantial language models through Ollama while maintaining fast inference speeds at 2600 MHz. The 256-bit memory bus ensures efficient data transfer when processing large model weights and generating tokens. This capacity allows users to run 13B parameter models comfortably or experiment with quantized versions of larger models, providing flexibility for those exploring various architectures available in the Ollama library.
Pros
- 16GB GDDR7 supports 20B-40B parameter models
- Tensor Cores improve inference speed over prior generations
- PCIe 5.0 accelerates model loading times
- WINDFORCE cooling handles continuous server operation
Cons
- Mid-tier positioning limits headroom for largest experimental models
- Triple-fan design requires adequate case ventilation
The 16GB GDDR7 memory on this GIGABYTE RTX 5070 Ti positions it as a compelling middle path for Ollama users who need serious VRAM capacity without stepping into flagship territory. That memory allocation supports models in the 20B to 40B parameter range comfortably, covering popular choices like Llama 3.1 and Mixtral variants that represent the sweet spot for local deployment. The 256-bit memory bus paired with GDDR7 technology provides bandwidth sufficient for inference workloads where data movement between memory and compute units can bottleneck performance on older architectures. NVIDIA's Blackwell improvements to Tensor Cores translate to measurable gains in token generation speed, particularly noticeable in longer context windows where older cards struggle. The WINDFORCE triple-fan system keeps thermals controlled during back-to-back inference sessions, important for users who maintain active Ollama servers responding to frequent queries. PCIe 5.0 connectivity reduces the wait time when loading multi-gigabyte model files into VRAM at startup. The 2600 MHz GPU clock provides solid compute throughput without the extreme power draw of higher-tier cards. At this performance level, the card handles continuous operation reliably while the three-fan design balances acoustic output against cooling efficiency, relevant for desktop workstations where noise matters.
Core Specs: GPU: NVIDIA GeForce RTX 5070 Ti (Blackwell Architecture) | Memory: 16GB GDDR7 | Memory Interface: 256-bit | GPU Clock: 2600 MHz | Memory Clock: 2600 MHz | PCIe: 5.0
Cooling and Power: WINDFORCE cooling system with 3 fans | Dimensions: 13.46" L x 5.59" W | Weight: 3.9 pounds
Outputs and Compatibility: Video Outputs: DisplayPort, HDMI | Max Resolution: 7680 x 4320 (8K) | Compatible with desktop systems | Interface: PCI-Express x16
Warranty: 3-year manufacturer warranty
Perfect for hobbyists and small-team developers who want to run substantial open-source models locally without committing to flagship expenses. The 16GB VRAM covers most practical use cases including fine-tuned models and extended context applications. Developers hosting Ollama servers for personal or small-group use gain excellent capability-per-dollar. Skip this if you exclusively work with compact 7B models that never stress VRAM limits, or if you need absolute maximum capacity for experimental 70B+ parameter research where the extra headroom justifies paying more.
What to Look for in a GPU for Ollama
VRAM Capacity
VRAM is the single most important spec when choosing a GPU for Ollama. Models load entirely into GPU memory, and if your card does not have enough, inference falls back to system RAM or simply refuses to run at full speed. A 7B model in full precision needs around 14GB, while quantized versions can squeeze into 8GB.
Cards like the ASUS TUF Gaming GeForce RTX™ 5080 16GB GDDR7 OC and the GIGABYTE GeForce RTX 5080 Gaming OC 16G Graphics both pack 16GB of GDDR7, giving you enough headroom to comfortably run 13B models in Q4 or Q5 quantization with tokens to spare.
Memory Bandwidth
Raw VRAM capacity tells only half the story. Memory bandwidth determines how quickly the GPU can feed data to its compute cores during inference, and this directly sets your tokens-per-second ceiling. GDDR7 memory, found on the latest Blackwell and RDNA 4 cards, delivers substantially higher bandwidth than older GDDR6X designs.
The GIGABYTE Radeon RX 9070 XT Gaming OC 16G Graphics runs on AMD’s RDNA 4 architecture with GDDR6 and PCIe 5.0, offering a compelling balance of bandwidth and capacity for the asking price. It is a strong choice if you prefer the AMD ecosystem or want ROCm compatibility for certain inference frameworks.
Architecture and AI Acceleration
Not all GPU compute is equal for AI workloads. NVIDIA’s Blackwell architecture introduces fourth-generation Tensor Cores alongside DLSS 4, and those Tensor Cores handle the matrix multiplications that dominate LLM inference. Cards like the ASUS TUF Gaming GeForce RTX 5070 12GB GDDR7 OC and the GIGABYTE GeForce RTX 5070 Ti Gaming OC 16G benefit directly from this hardware acceleration.
CUDA support also matters here. Ollama’s default backend is optimized for CUDA, which means NVIDIA cards typically deliver better out-of-the-box performance with zero extra configuration compared to AMD alternatives, though ROCm support has improved considerably in recent releases.
Budget vs. Capability Tradeoffs
Not every Ollama user needs a flagship card. The HP NVIDIA Tesla M60 16GB Server GPU Accelerator is a renewed enterprise card that packs 16GB of VRAM at a fraction of the cost of a new consumer GPU. It lacks modern AI acceleration features, but for users who primarily need raw VRAM to load larger models and are not chasing maximum tokens per second, it is a pragmatic option worth evaluating.
Keep in mind that server-class cards like the Tesla M60 are passively cooled and were designed for rack-mounted environments, so you will need adequate case airflow. Pairing this with a solid understanding of your hardware budget, similar to how RC enthusiasts weigh options in our RC and Drones section, helps you avoid overspending on specs you will not use.
Final Thoughts
For most users running Ollama at home, the sweet spot sits between a capable mid-range card and a true flagship, depending on which model sizes you want to run comfortably. If you want the best overall balance of VRAM, modern AI acceleration, and energy efficiency, the ASUS TUF Gaming GeForce RTX 5070 12GB GDDR7 OC is a well-rounded pick for 7B and many 13B models, while power users who need to run larger models without quantization compromises will find the ASUS TUF Gaming GeForce RTX™ 5080 16GB GDDR7 OC worth the investment for its headroom and raw throughput.
Frequently Asked Questions
How much VRAM do I need to run Ollama?
It depends on the model size and quantization level you plan to use. For most 7B models in Q4 quantization, 8GB of VRAM is sufficient, but 12GB to 16GB gives you much more flexibility. If you want to run 13B or 30B models without heavy quantization, aim for at least 16GB.
Can I use an AMD GPU with Ollama?
Yes, Ollama supports AMD GPUs through ROCm on Linux. The GIGABYTE Radeon RX 9070 XT Gaming OC 16G Graphics is a capable modern AMD option with 16GB of memory. Windows ROCm support is more limited, so Linux is recommended if you go the AMD route for AI inference in 2026.
Is a refurbished server GPU a good choice for running local LLMs?
A renewed enterprise card can be a cost-effective way to get a large VRAM pool without a high upfront cost. The tradeoff is that older server GPUs lack modern Tensor Core acceleration, which means your tokens-per-second rate will be lower than a current-generation consumer card with the same VRAM amount. For casual or low-latency-tolerant use cases, it can still be a practical option worth considering.
Does the GPU matter more than the CPU for Ollama performance?
When a model fits entirely in VRAM, the GPU dominates performance and the CPU becomes largely a bystander. The CPU only becomes a bottleneck when models overflow into system RAM and Ollama falls back to CPU inference, which is dramatically slower. Prioritizing GPU VRAM over CPU specs is the right call for a dedicated Ollama workstation in 2026. For more context on balancing component choices across different electronics builds, the Graphics Cards category has additional guidance.




Write Your Review
No reviews yet. Be the first to share your experience!